Showing 120 of 120on this page. Filters & sort apply to loaded results; URL updates for sharing.120 of 120 on this page
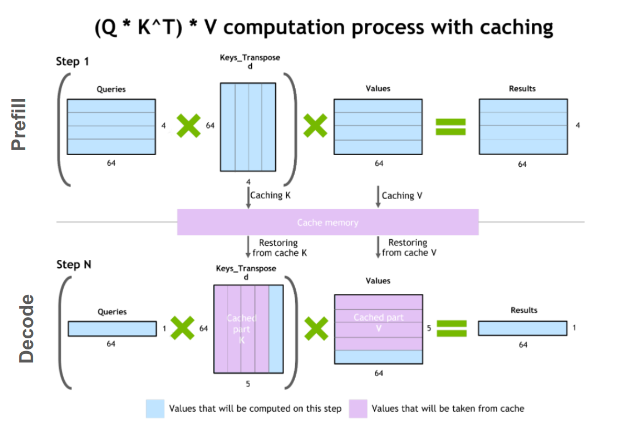
LLM Inference: Accelerating Long Context Generation with KV Cache ...
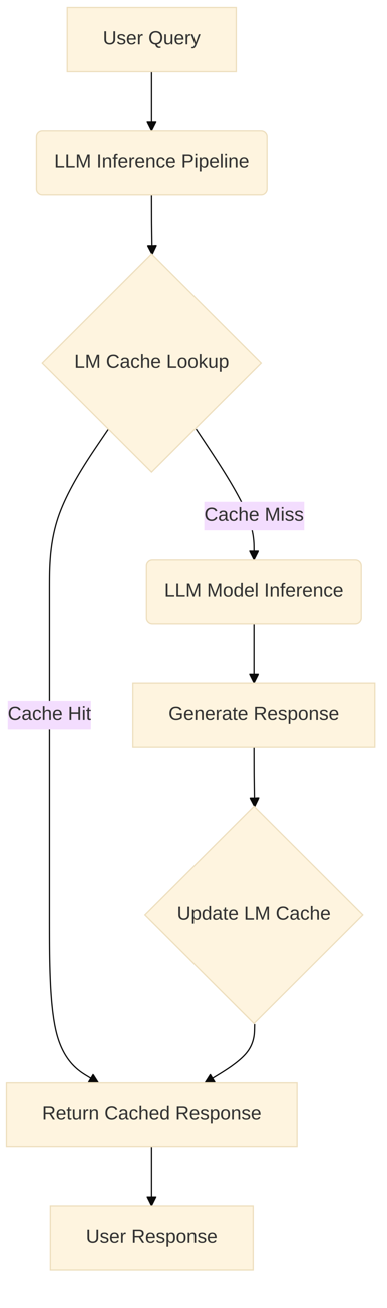
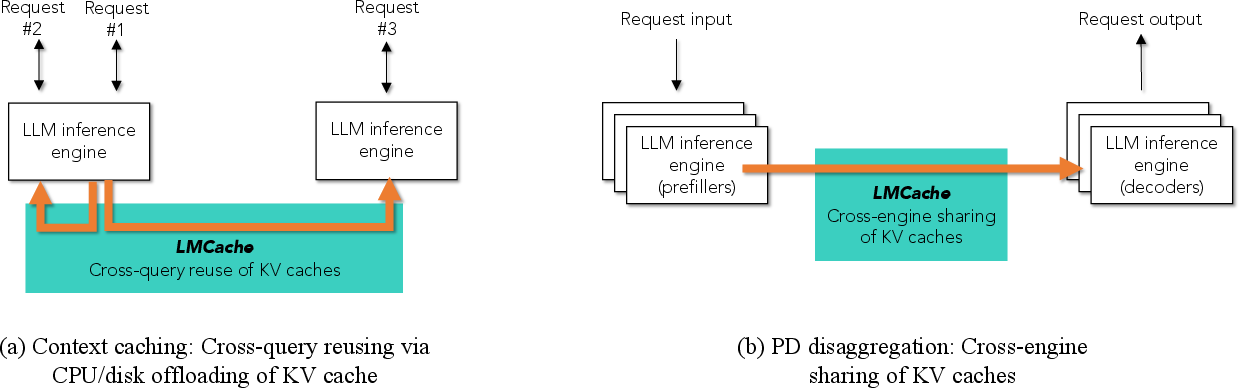
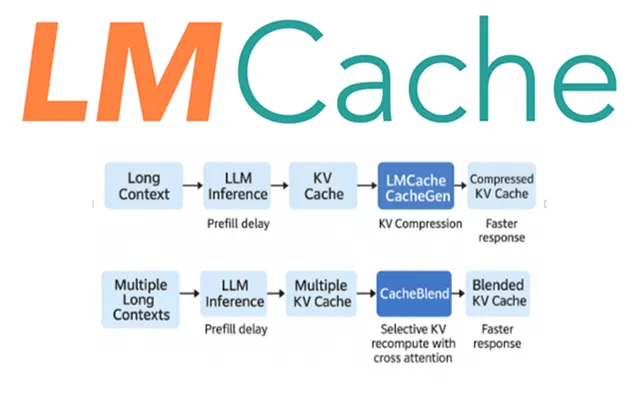
LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference ...
Оптимизация производительности LLM с Cache LM: архитектуры, стратегии и ...
KV-Runahead: Scalable Causal LLM Inference by Parallel Key-Value Cache ...
LMCache: Efficient KV Cache for LLM Inference
[PDF] LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM ...
KV Cache Meets NVMe: The Key to Accelerating LLM Inference
LLM 和 KV cache 详解 | Jasmine
Optimizing LLM Inference: Managing the KV Cache | by Aalok Patwa | Medium
LLM Inference Bottleneck: KV Cache vs Model Weights | Vinjam ...
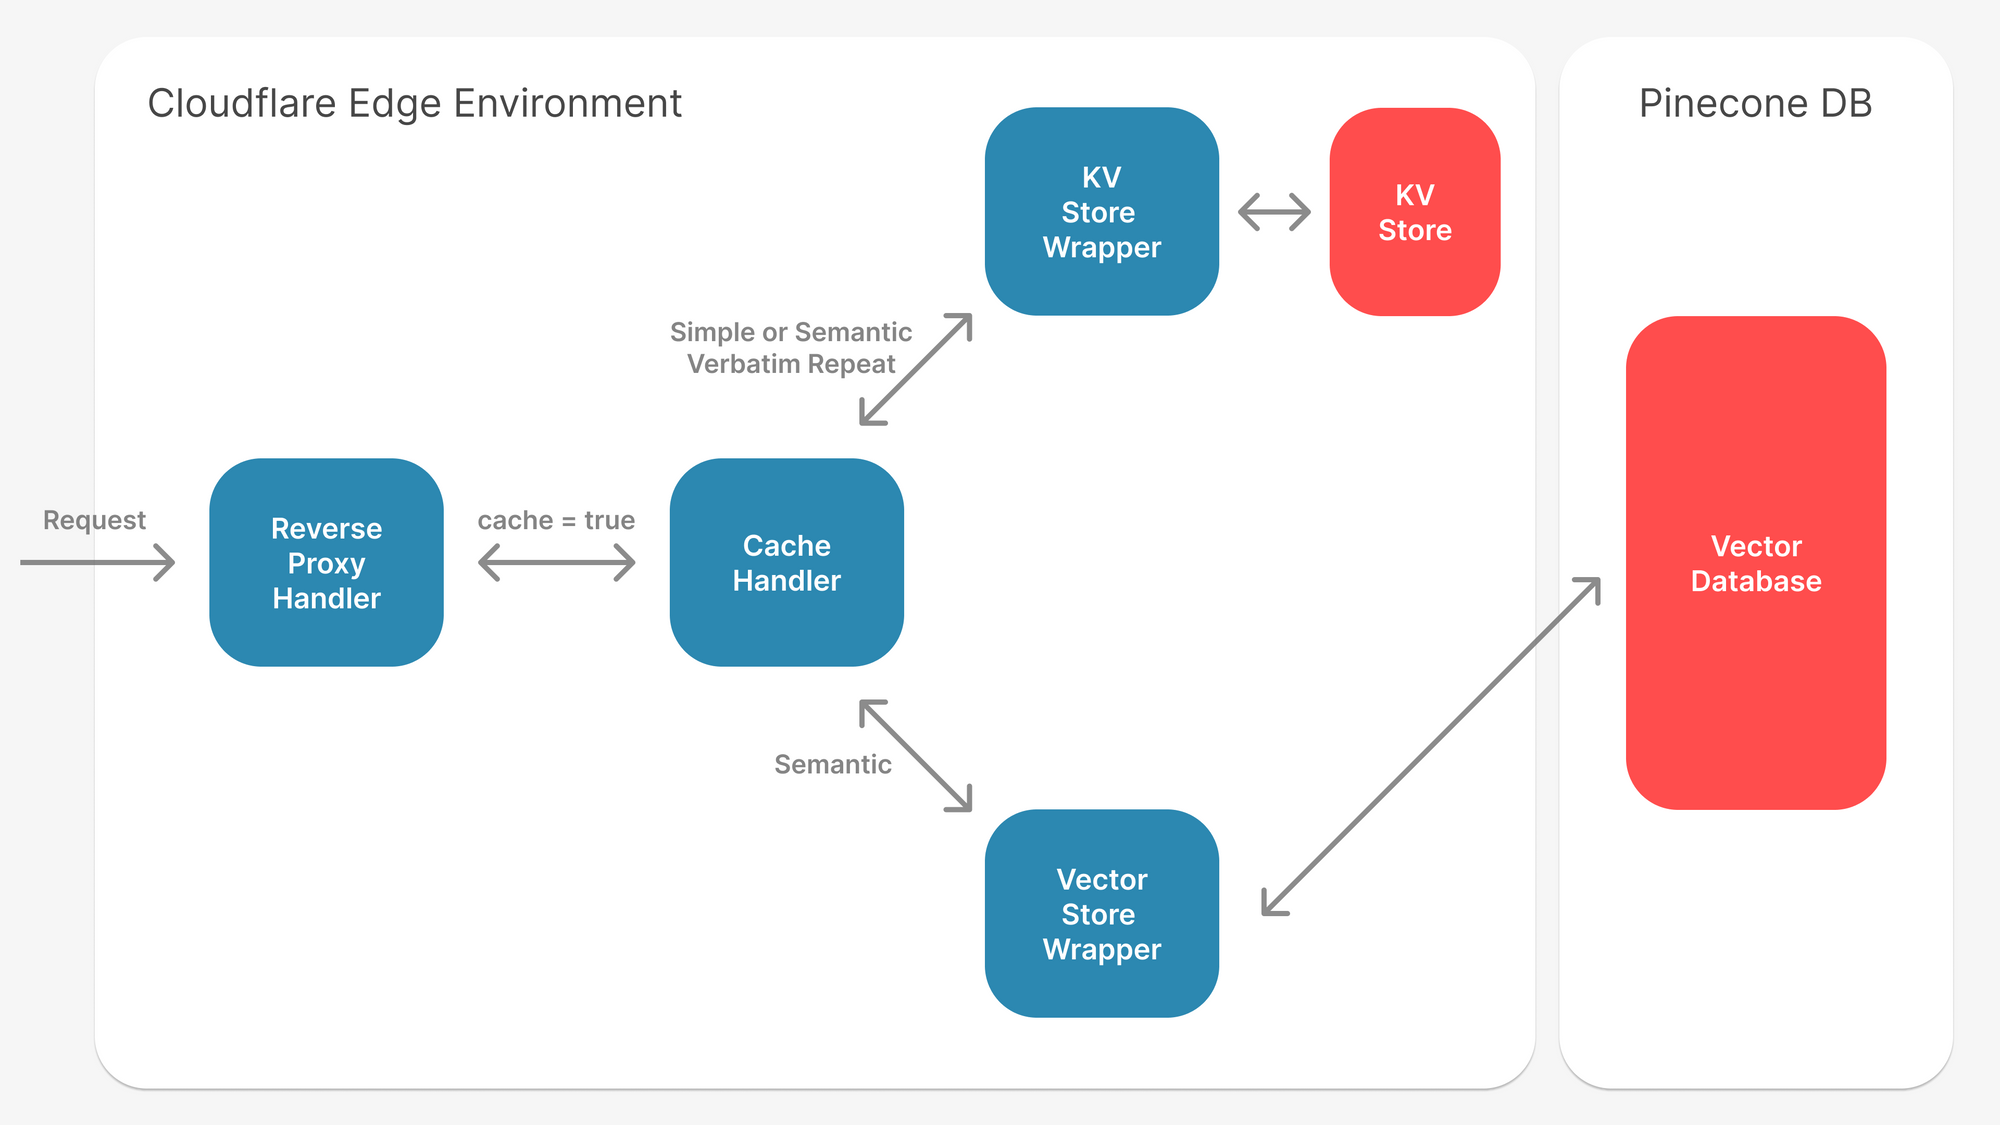
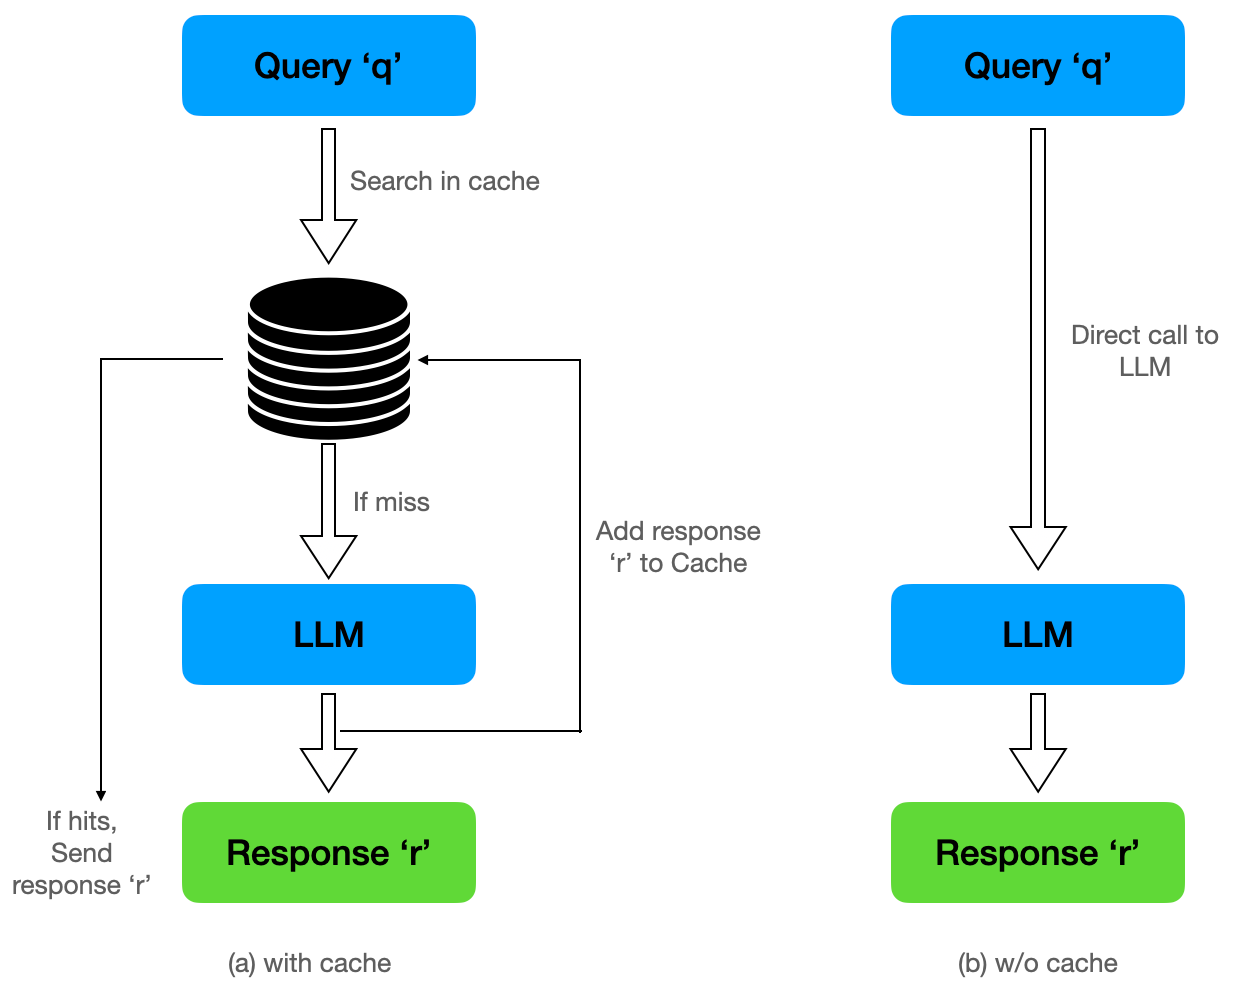
Open-Source Semantic Cache for LLM Applications | Eugene Okhrits posted ...
基于全局 KV Cache 存储系统的高效 LLM 推理加速方案 Efficient LLM Inference Acceleration ...
LLM Inference — Optimizing the KV Cache for High-Throughput, Long ...
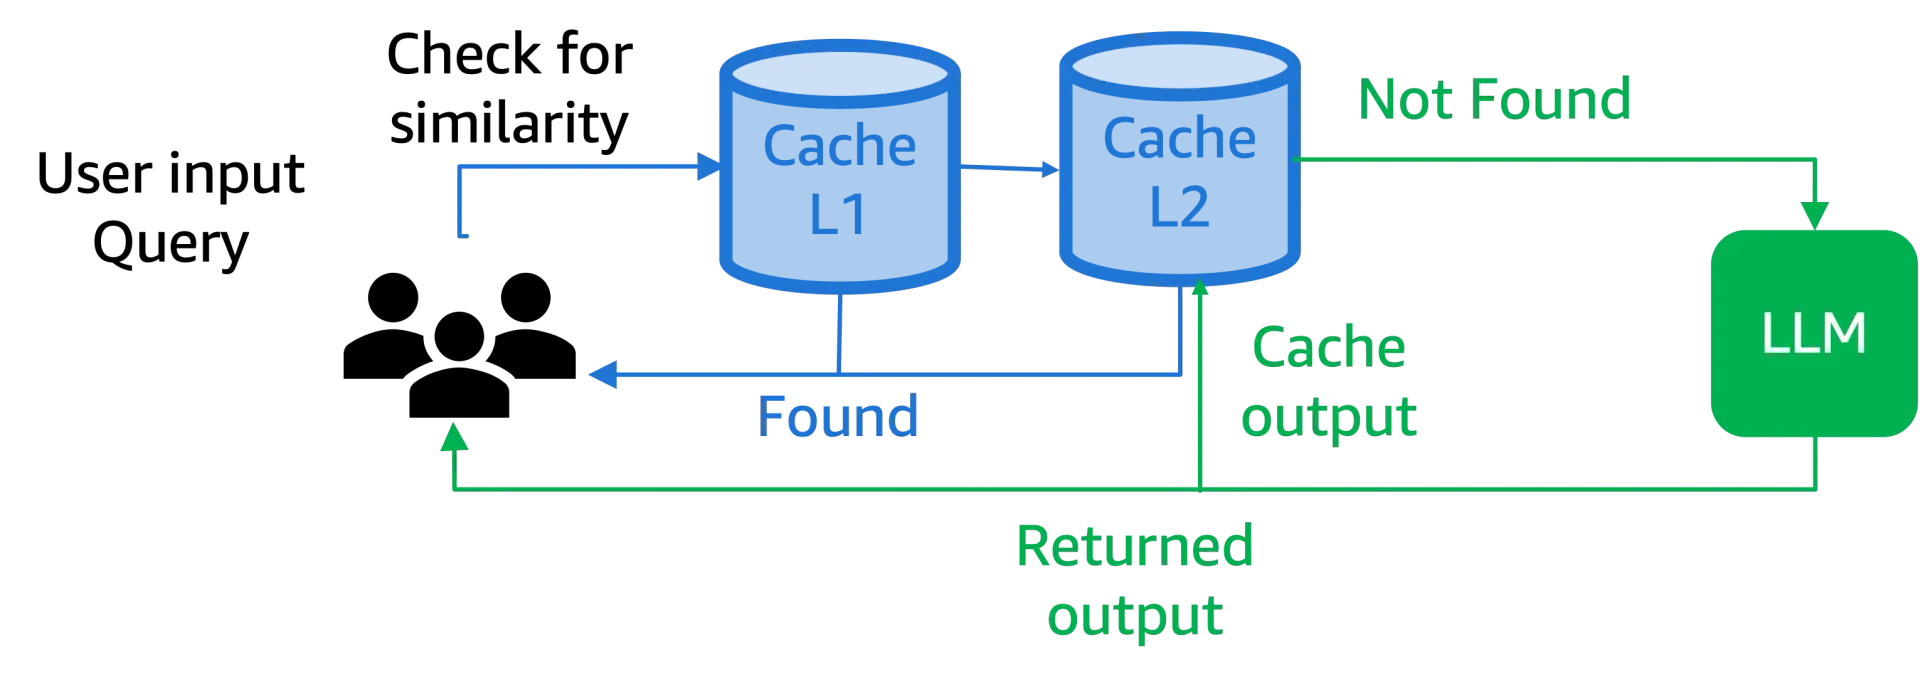
Inside a Multi-Layer Semantic Cache for Faster and Cheaper LLM ...
Accelerate Large-Scale LLM Inference and KV Cache Offload with CPU-GPU ...
Scaling Multi-Turn LLM Inference with KV Cache Storage Offload and Dell ...
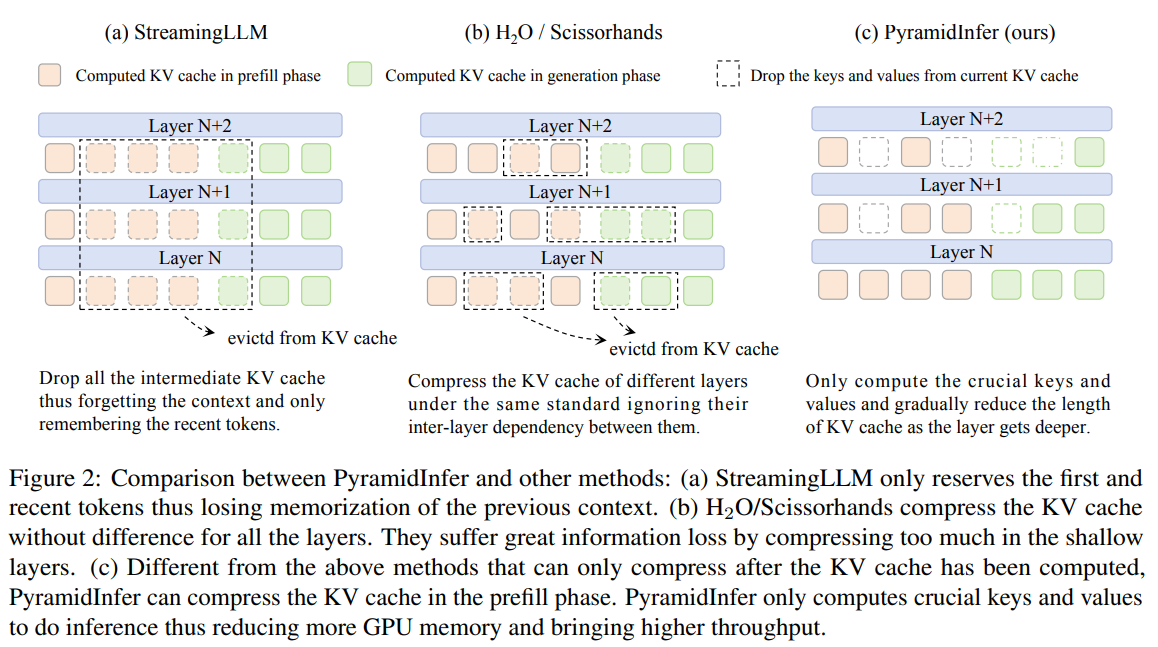
PyramidInfer: Allowing Efficient KV Cache Compression for Scalable LLM ...
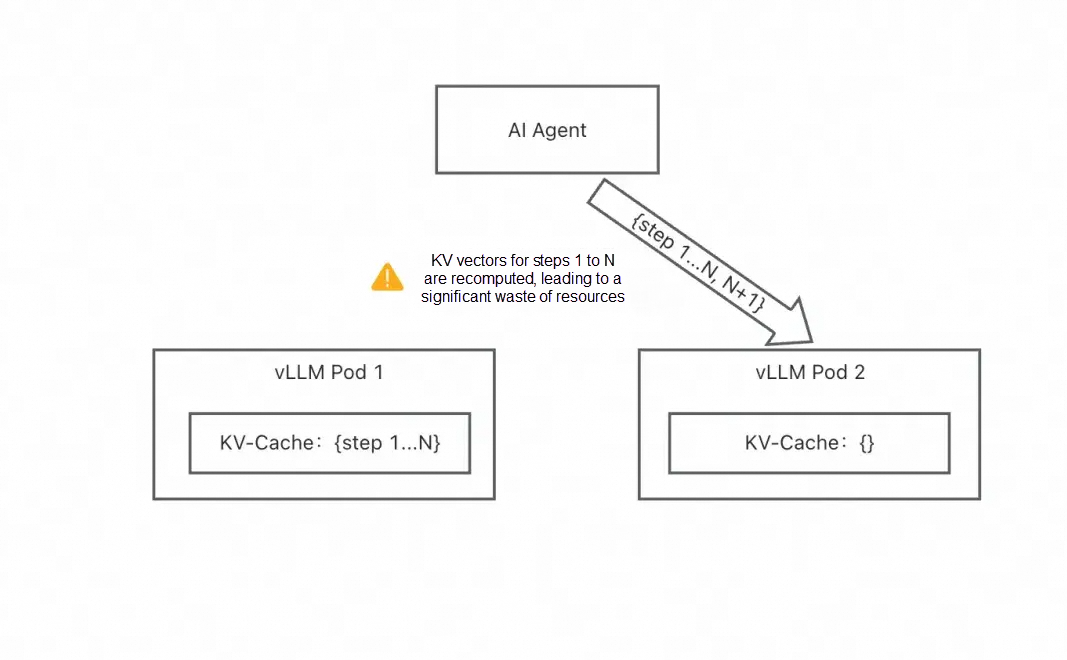
Caching is Efficiency: Achieving Precise LLM Cache Hits with Alibaba ...
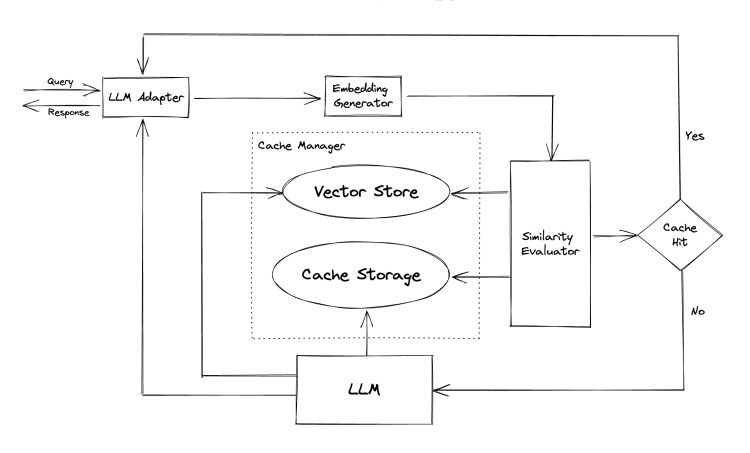
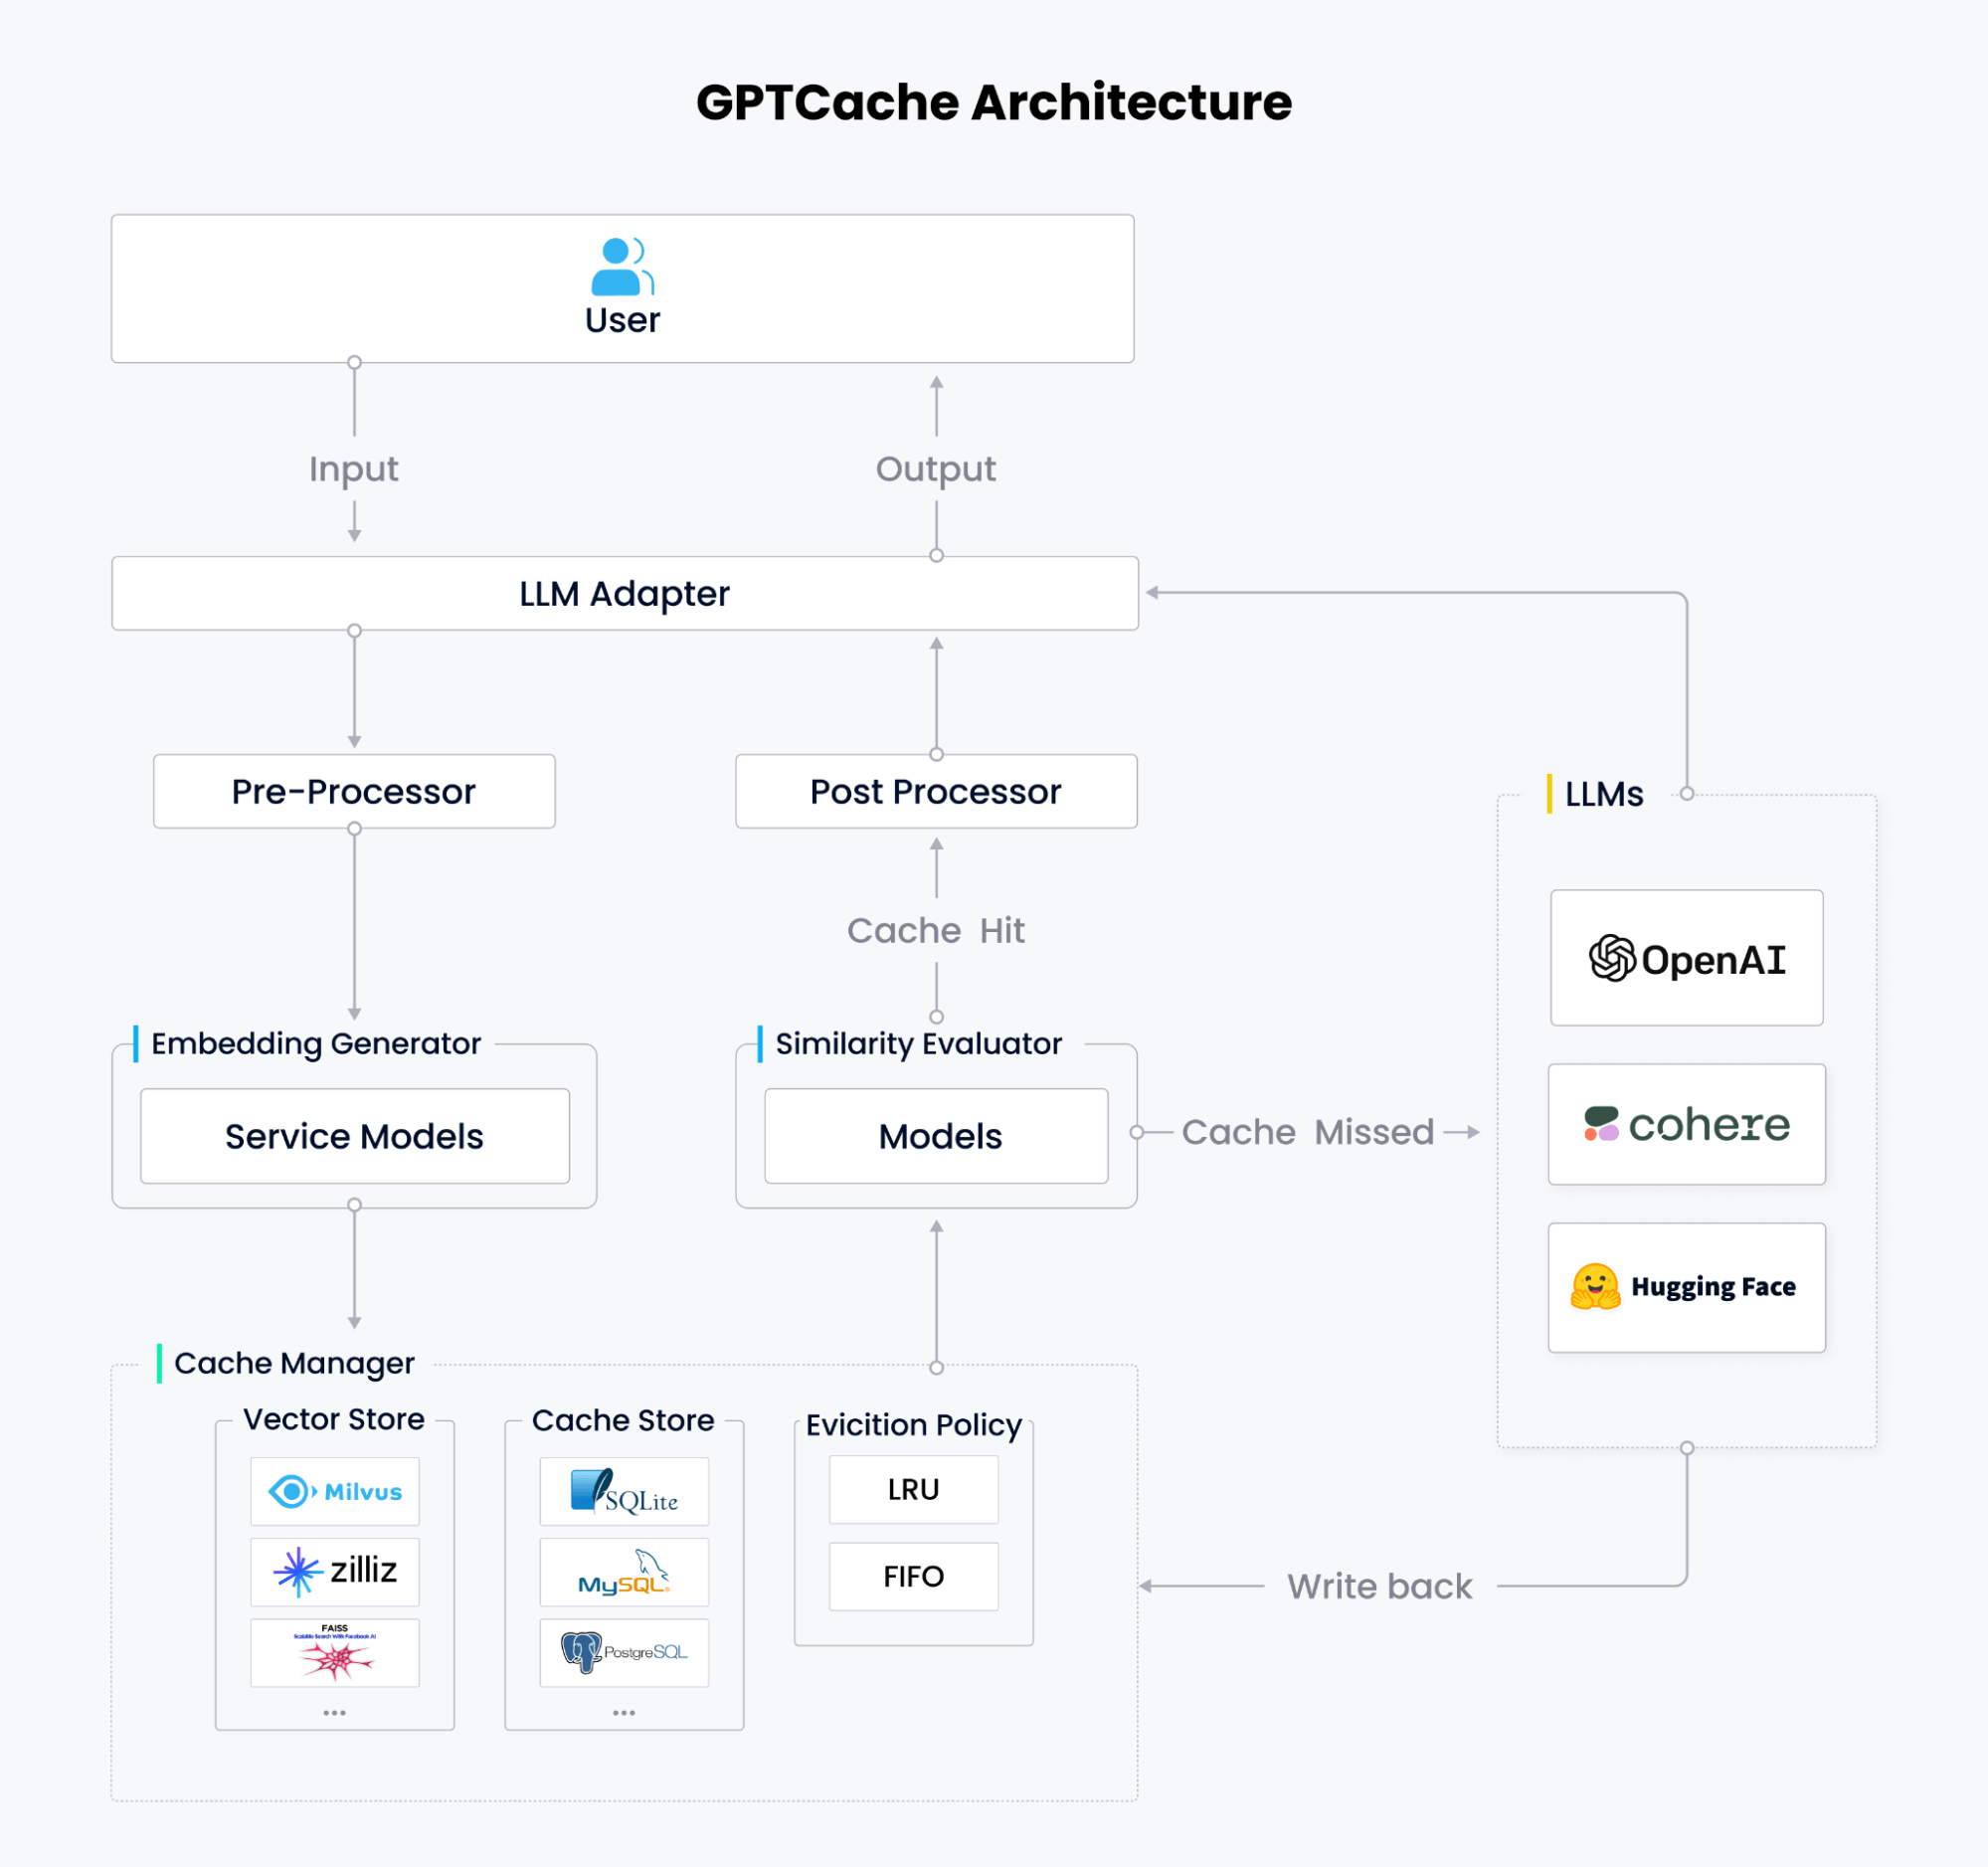
Figure 1 from GPTCache: An Open-Source Semantic Cache for LLM ...
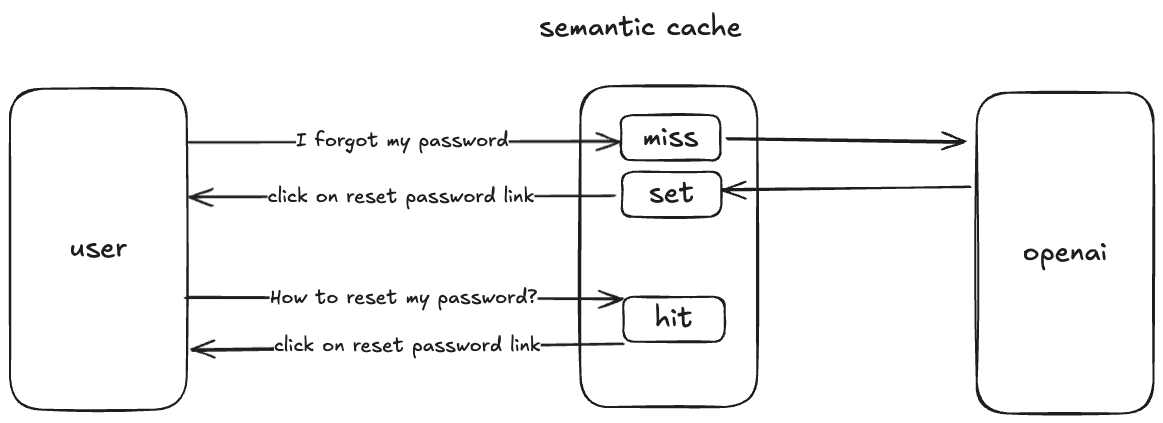
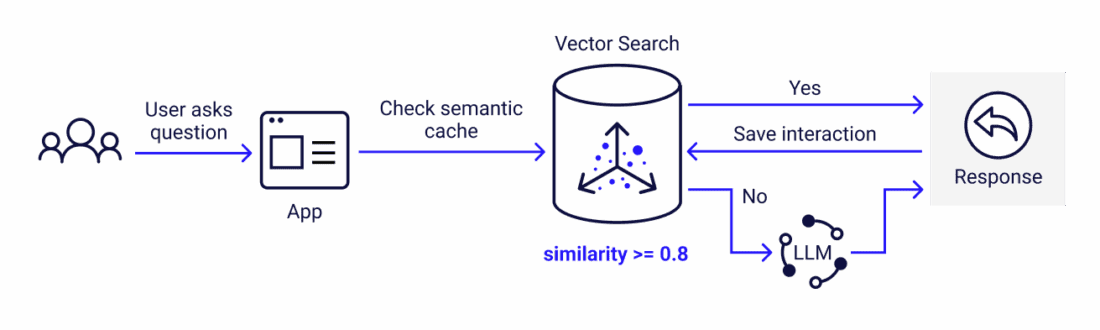
Semantic Cache Explained: A Simple Way to Optimize LLM Applications
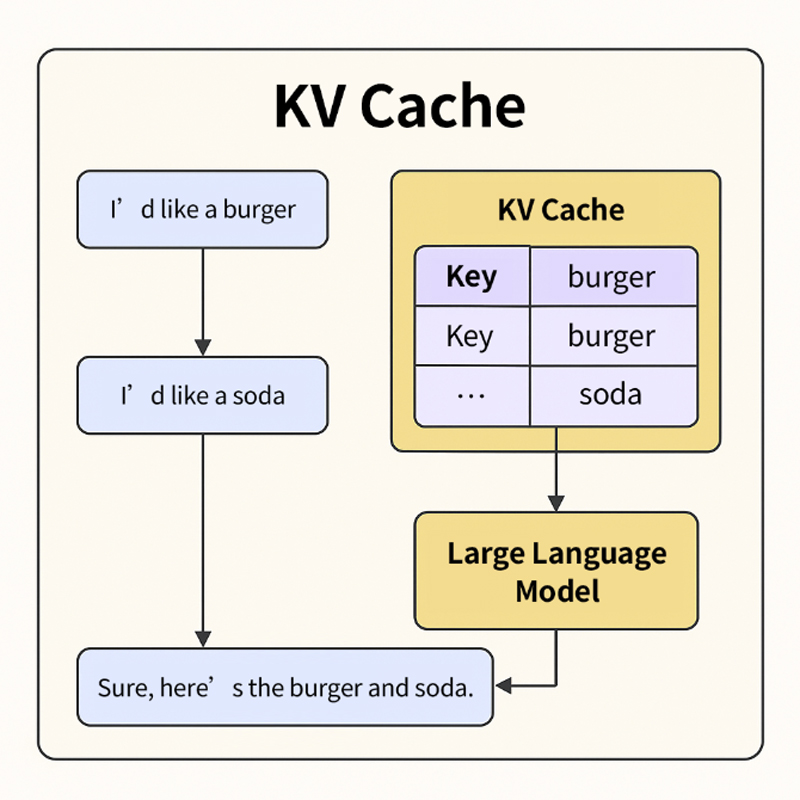
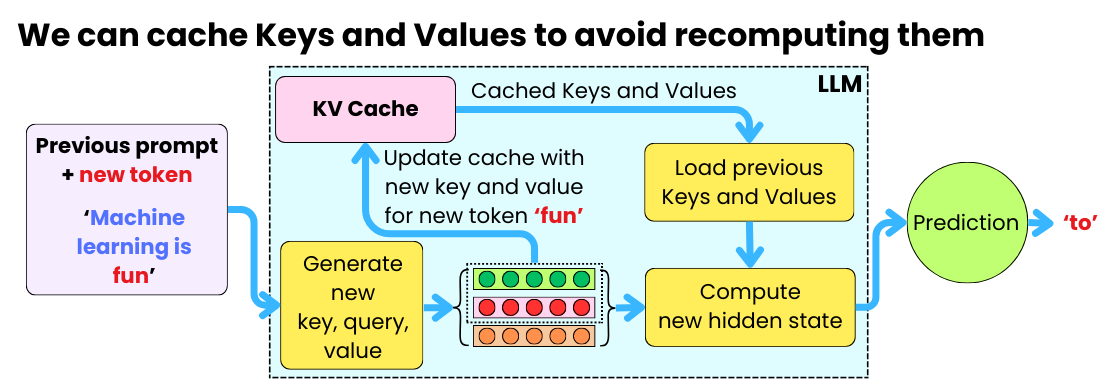
The Hidden Trick That Makes Every LLM Fast: Understanding the KV Cache ...
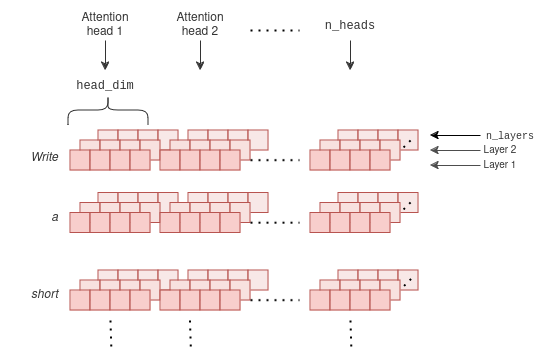
KV Cache Explained: Efficient Attention for LLM Generation ...
Improve LLM Performance Using Semantic Cache with Cosmos DB ...
Boost LLM Performance with Layered Cache Strategies | Mahesh ...
KV Cache Offload Accelerates LLM Inference - NADDOD Blog
KV Cache 详解:新手也能理解的 LLM 推理加速技巧-CSDN博客
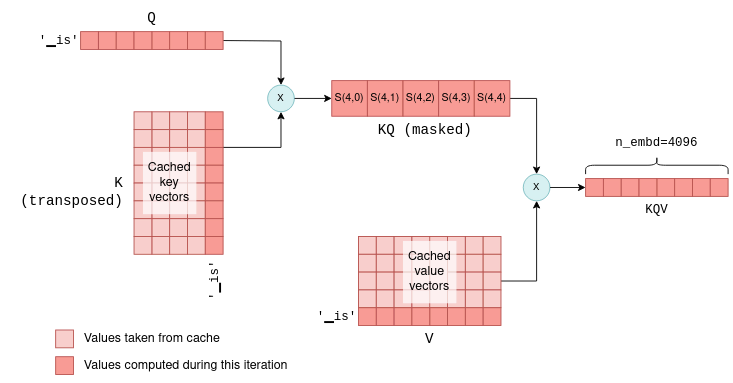
Understanding and Coding the KV Cache in LLMs from Scratch
The Beginner’s Guide to Semantic Caching in LLM Systems
LLM Inference Series: 4. KV caching, a deeper look | by Pierre Lienhart ...
Prompt Caching di Sistem LLM
What we learned building a Semantic Cache for LLMs
LMCache: Accelerating LLM Inference with Smart KV Caching (Part 1 of 2 ...
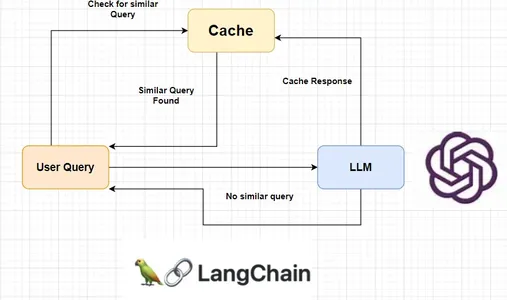
Build Faster and Cheaper LLM Apps With Couchbase and LangChain - The ...
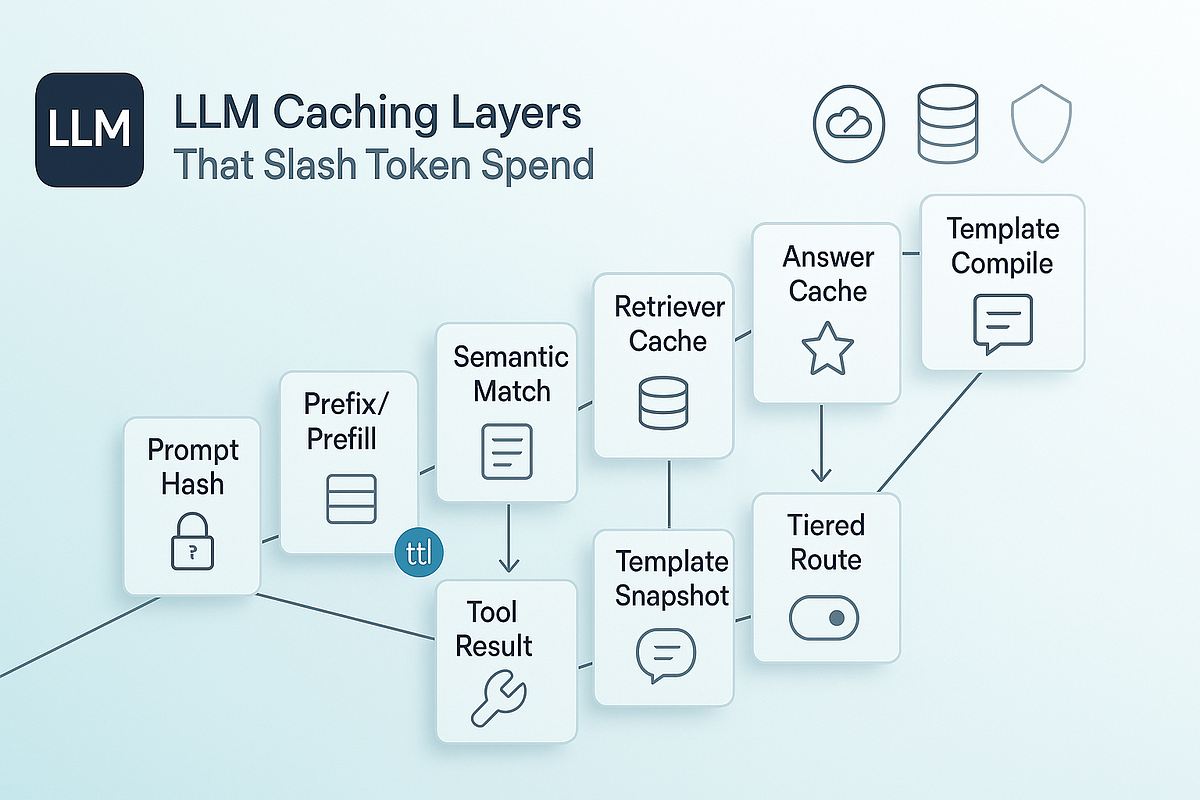
10 LLM Caching Layers That Slash Token Spend | by Syntal | Medium
Optimizing LLM Performance with LM Cache: Architectures, Strategies ...
AI/ML Infra Meetup | A Faster and More Cost Efficient LLM Inference ...
LMCache Is Becoming the De Facto Standard for KV Cache Management in ...
Semantic Cache for Large Language Models
How to Scale LLM Inference - by Damien Benveniste
How to Implement Effective LLM Caching
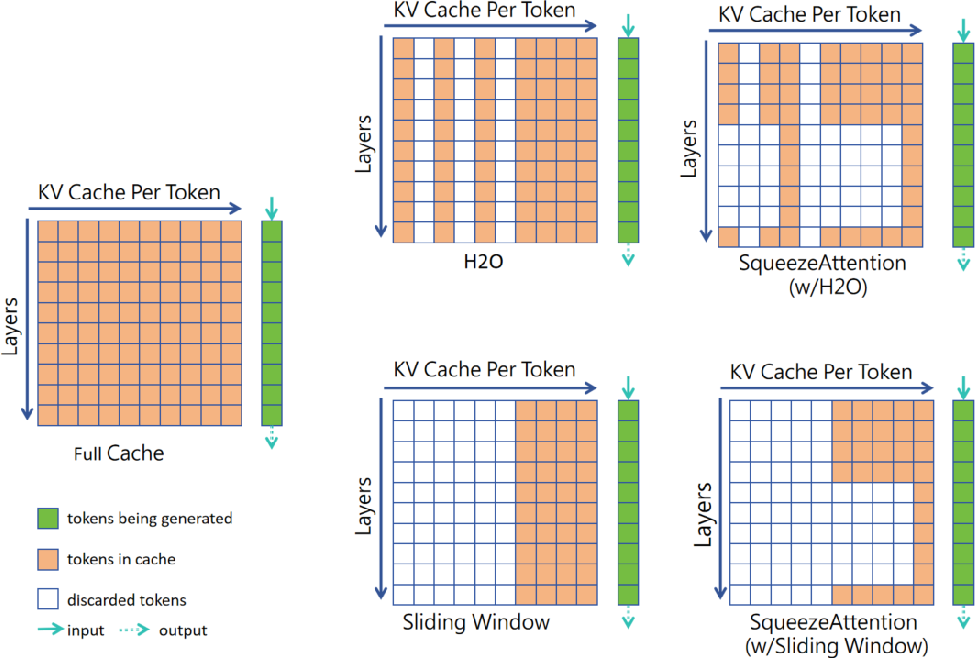
Figure 1 from SqueezeAttention: 2D Management of KV-Cache in LLM ...
5x Faster Time to First Token with NVIDIA TensorRT-LLM KV Cache Early ...
The Shift to Distributed LLM Inference: 3 Key Technologies Breaking ...
LLM 서비스 최적화: 리전 로드밸런싱과 캐싱 | Swalloow Blog
Optimize LLM Applications: Semantic Caching for Speed and Savings ...
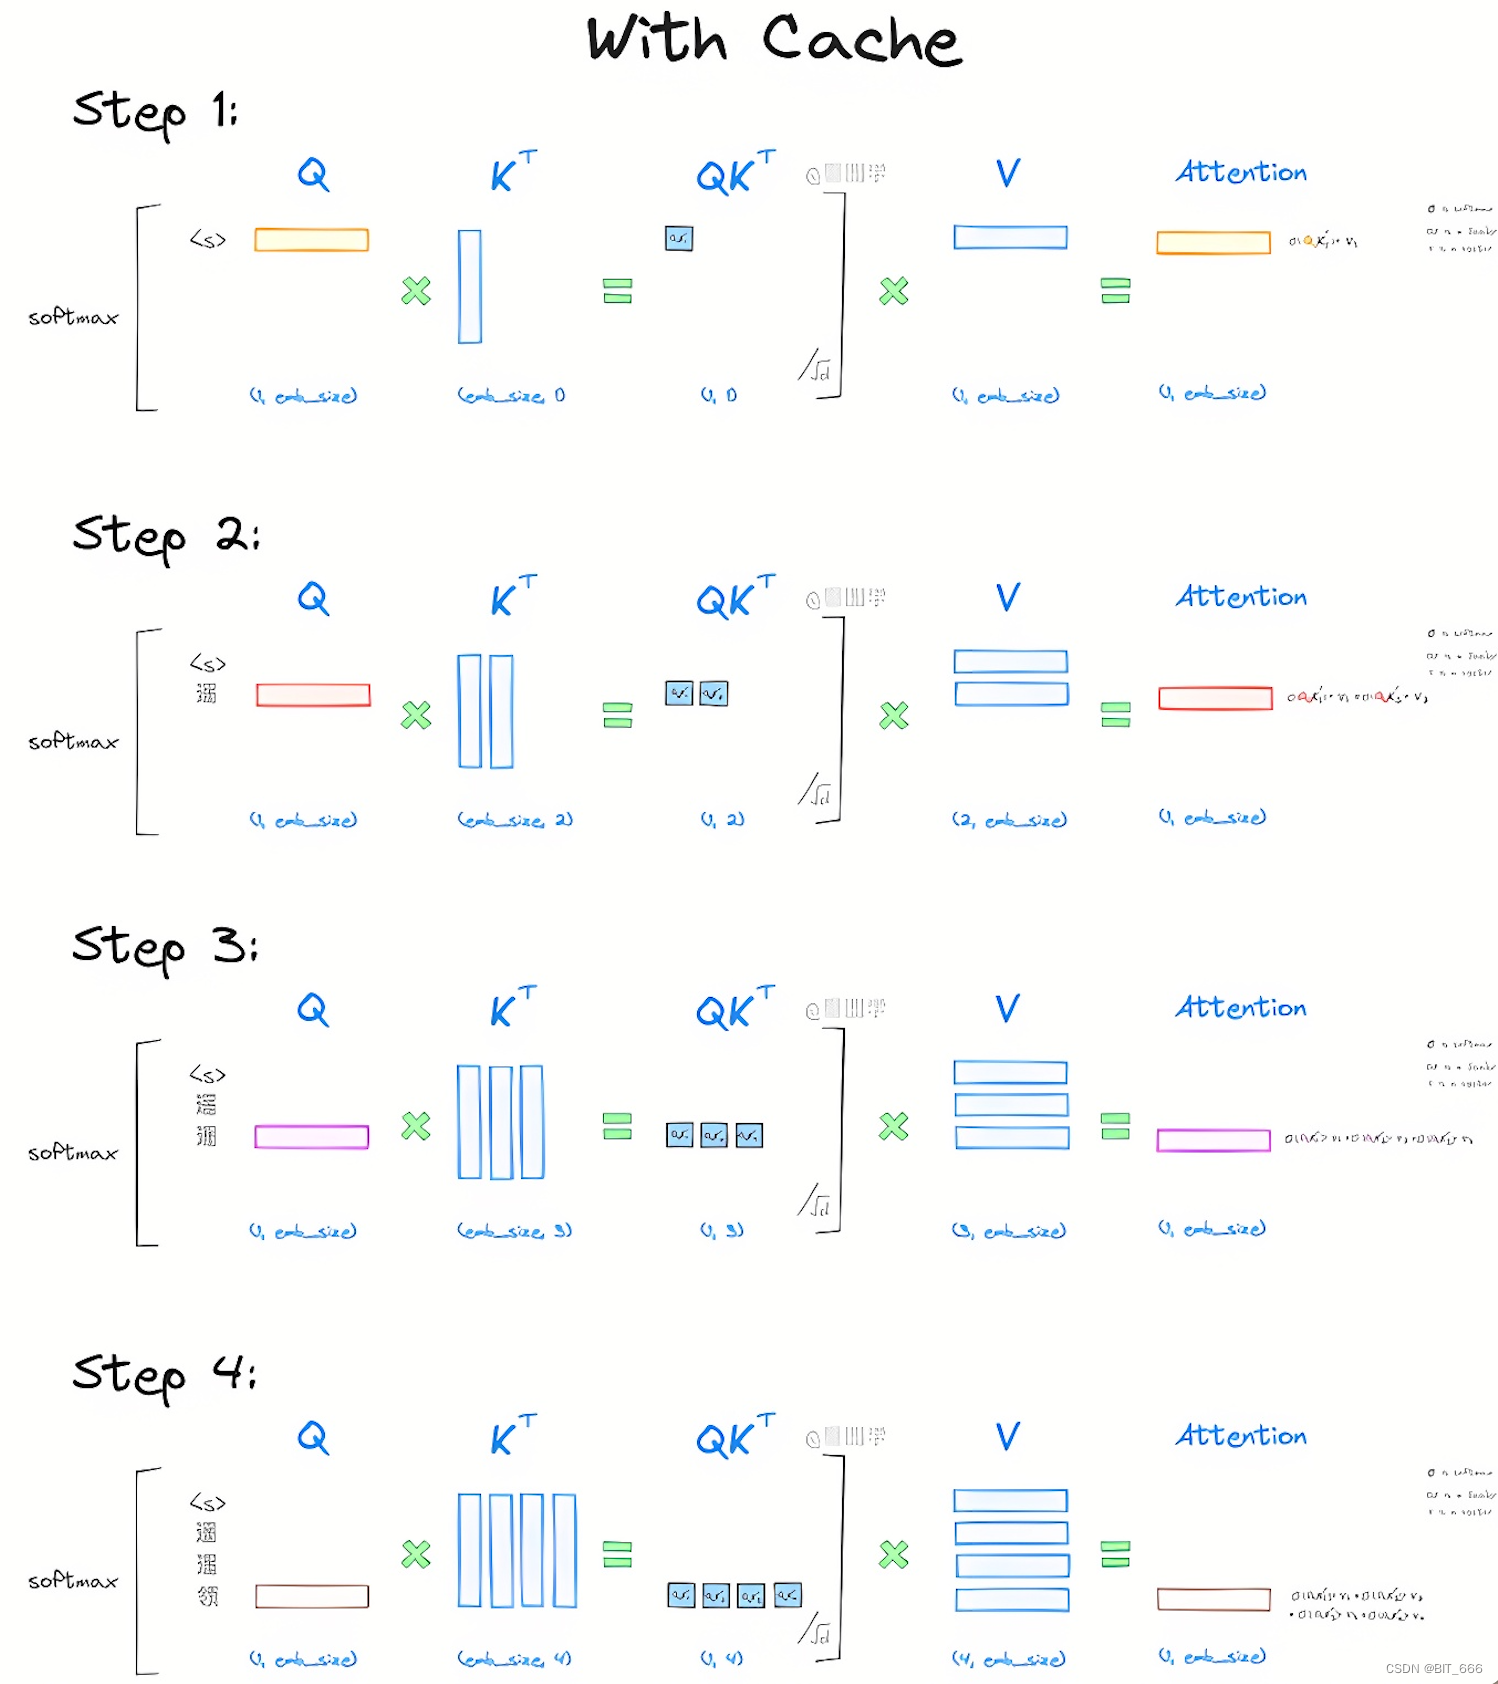
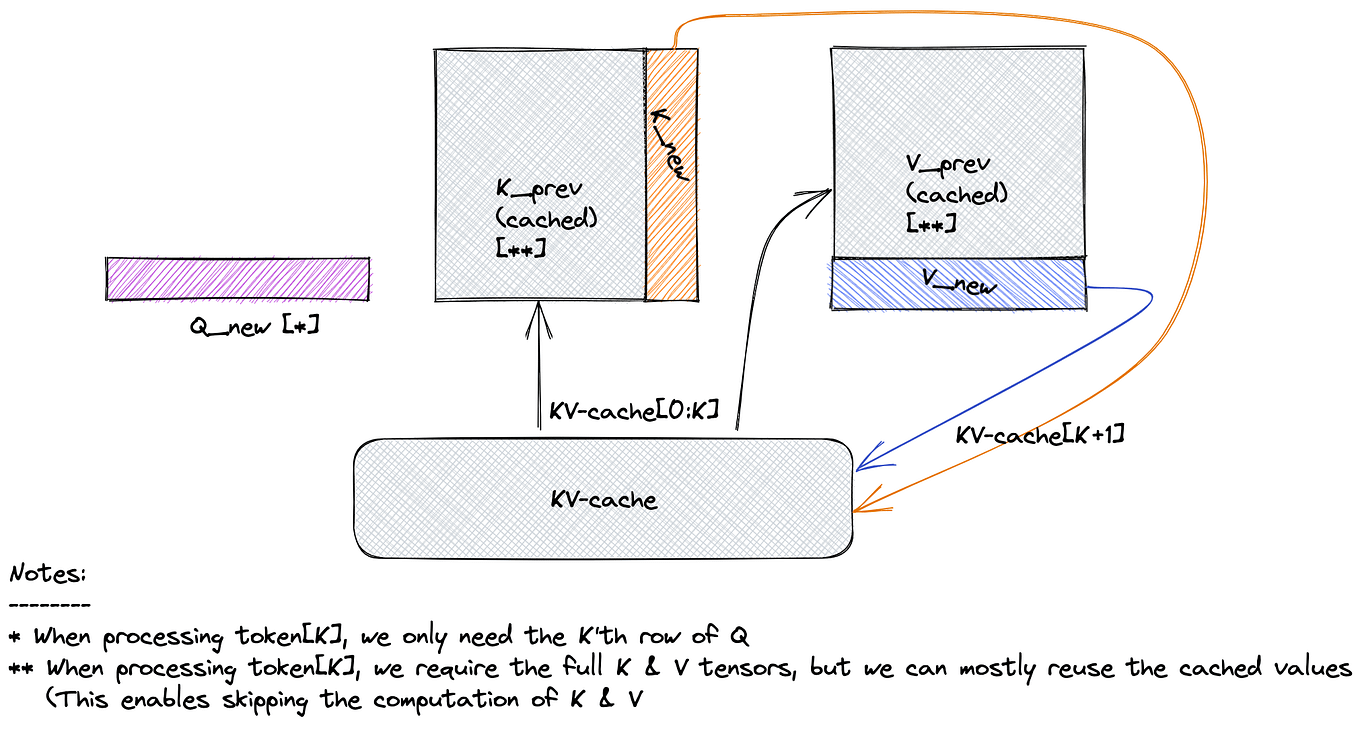
LLM - Generate With KV-Cache 图解与实践 By GPT-2_llm kv cache-CSDN博客
Techniques for KV Cache Optimization in Large Language Models
LLM Inference Series: 3. KV caching explained | by Pierre Lienhart | Medium
Key Concepts in Efficient LLM Inference | by Sebastian Pineda Arango ...
Deploying Distributed LLM Inference Service with IBM Storage Scale for ...
LLM Caching Layers : Key Value vs Semantic Caching
掌握 LLM 技术:推理优化 - NVIDIA 技术博客
[논문 리뷰] TokenLake: A Unified Segment-level Prefix Cache Pool for Fine ...
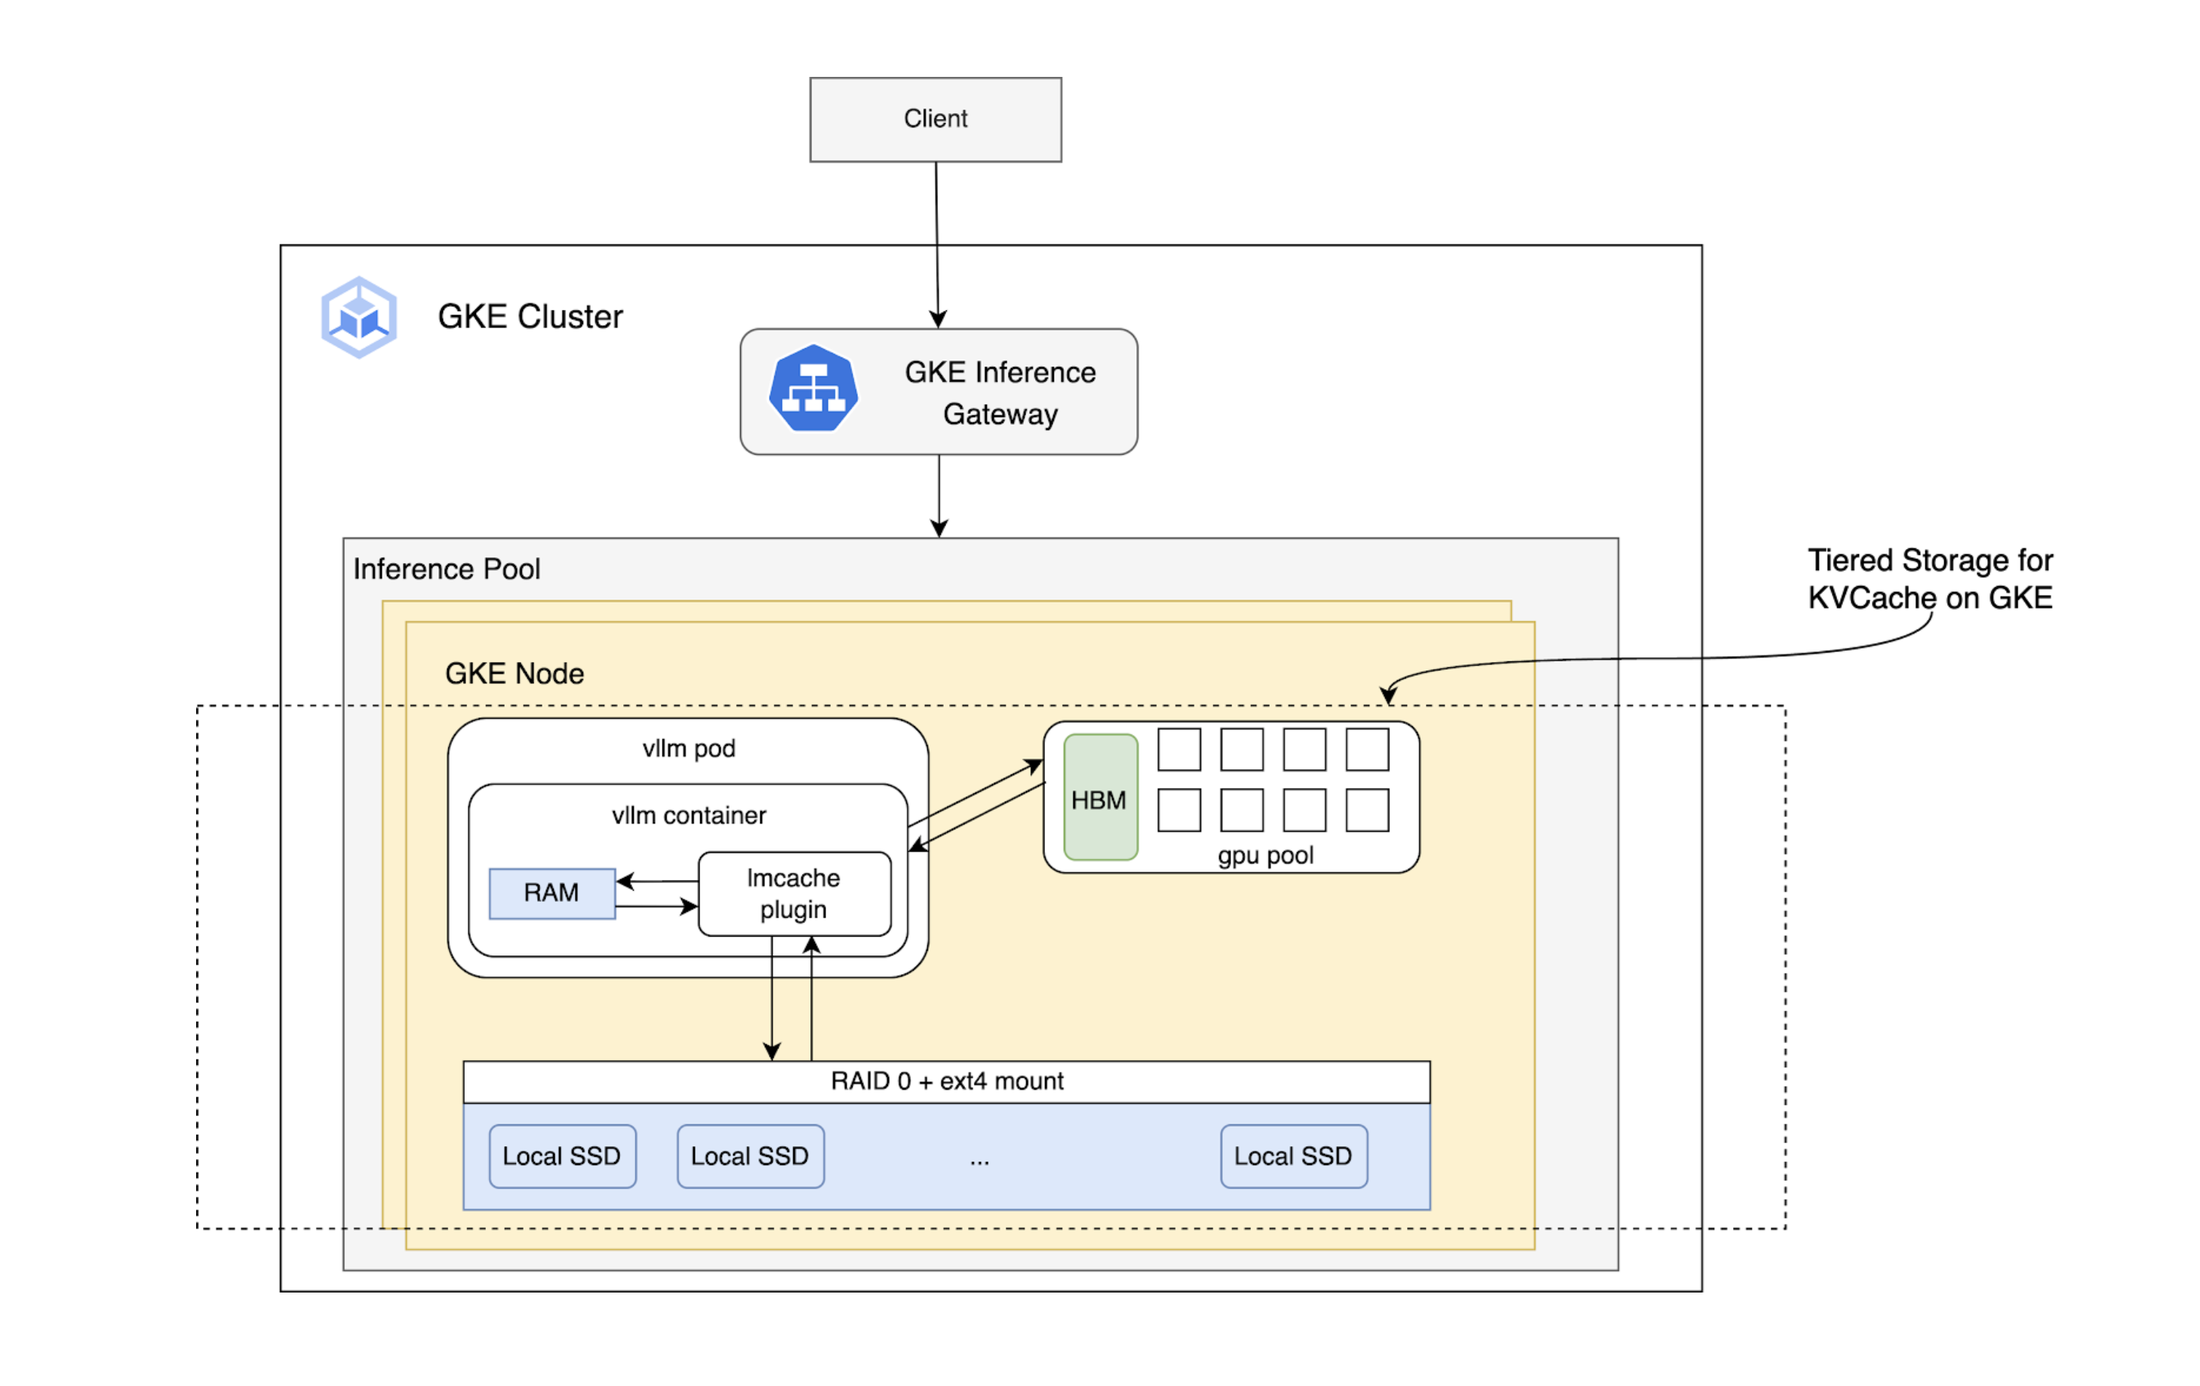
Google Kubernetes Engine の階層化 KV キャッシュで LLM のパフォーマンスを向上させる | Google ...
Fast and Expressive LLM Inference with RadixAttention and SGLang ...
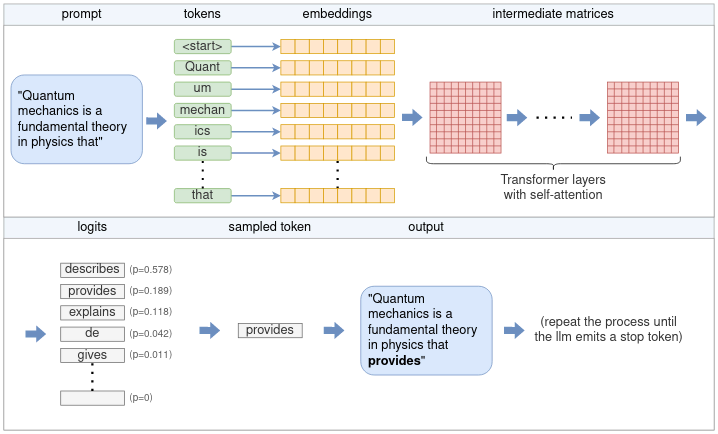
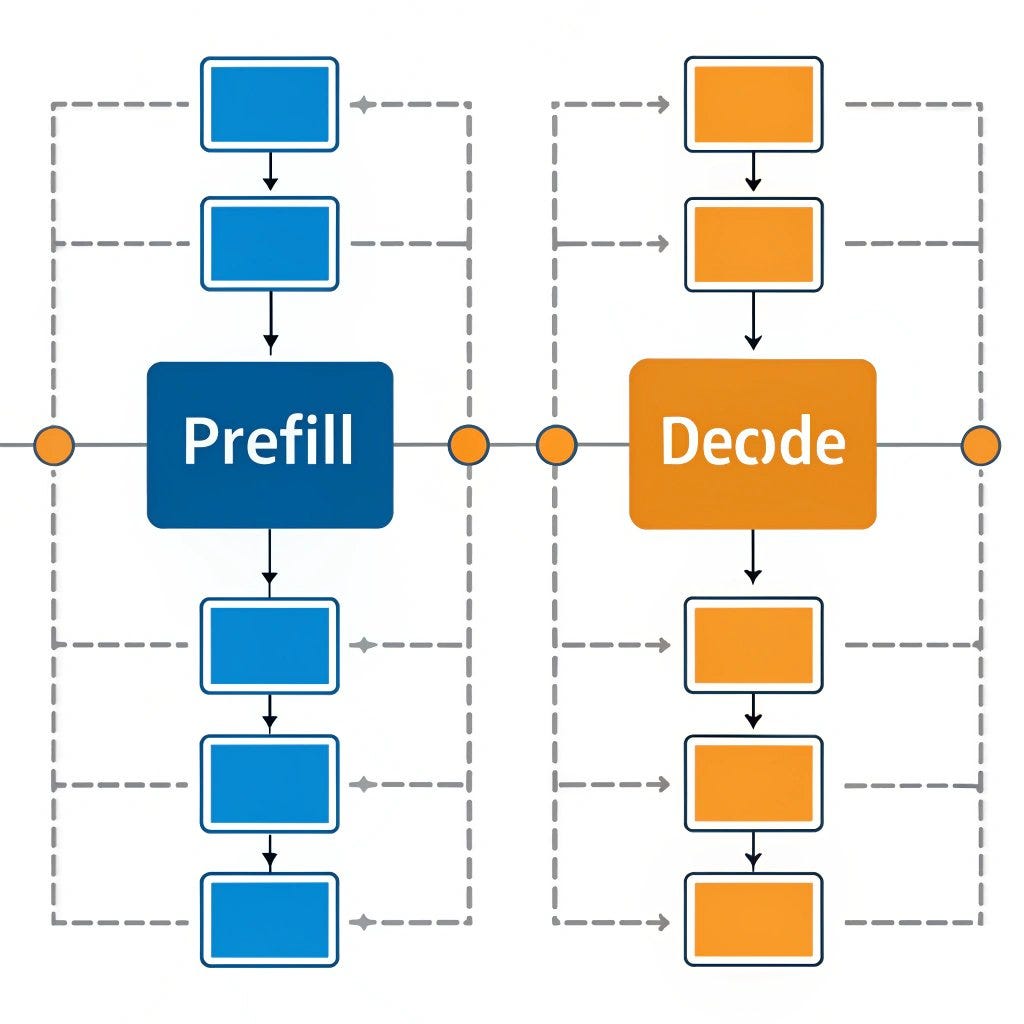
LLM Inference Series: 2. The two-phase process behind LLMs’ responses ...
GitHub - Talgonen/LLM_cache_project: Semantic cache for LLMs. Fully ...
LLM - Generate With KV-Cache 图解与实践 By GPT-2_gpt2 kv缓存的使用和实现-CSDN博客
LLM Inference Optimization 101 | DigitalOcean
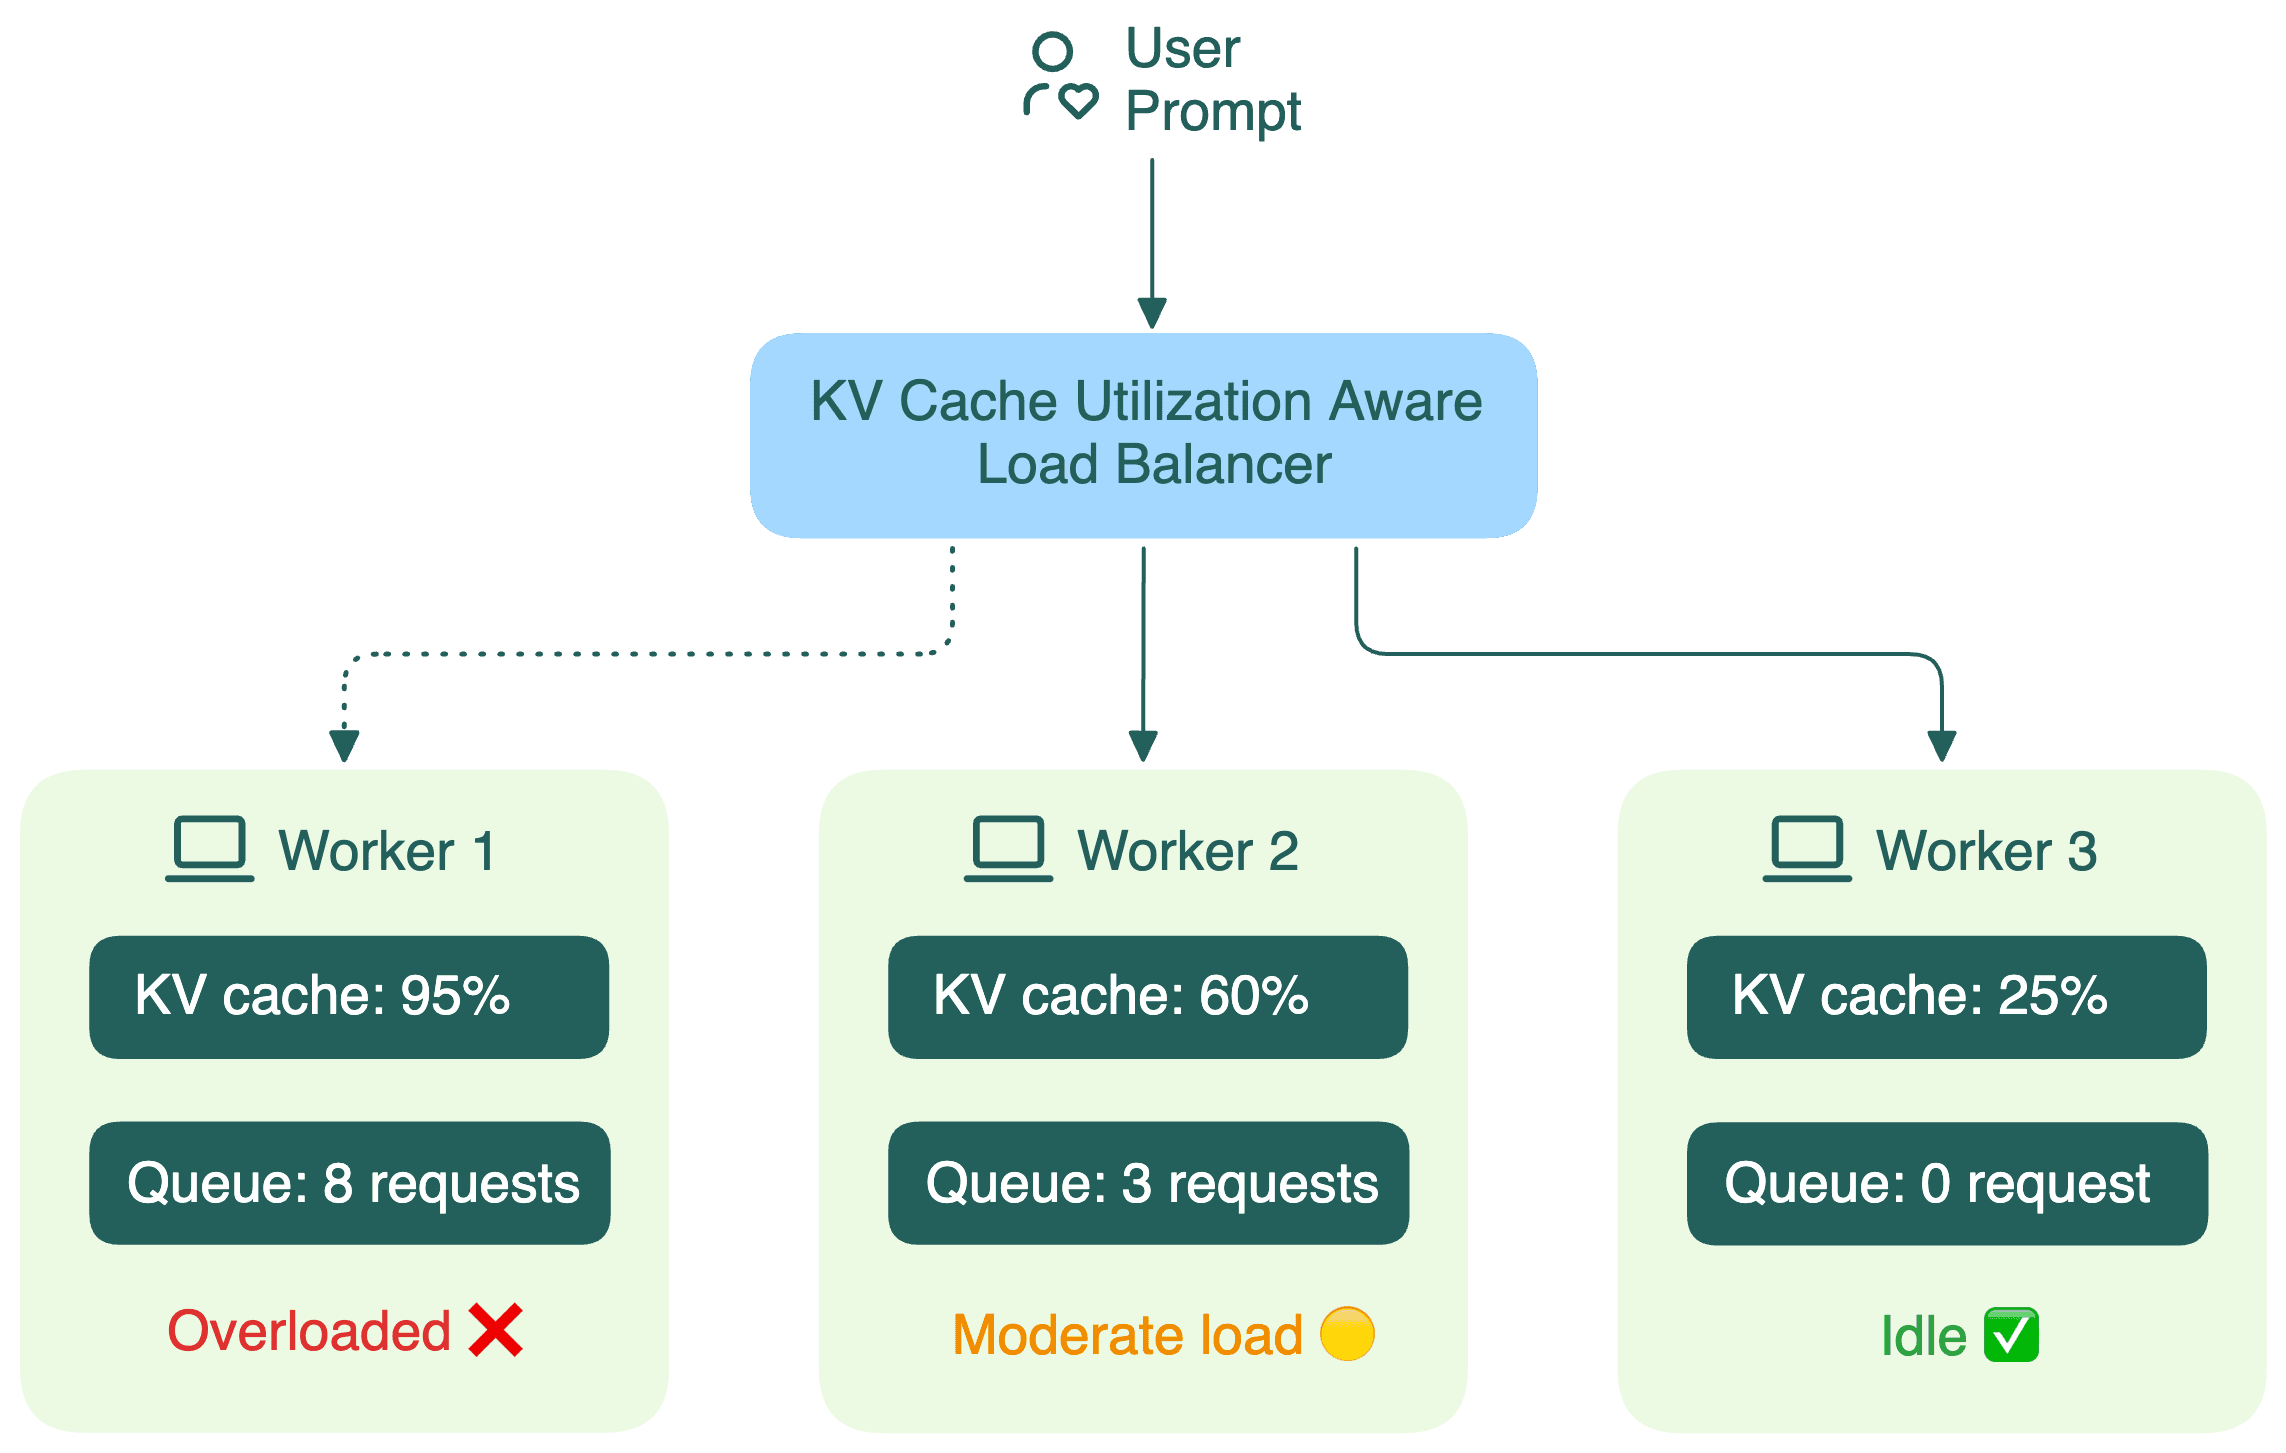
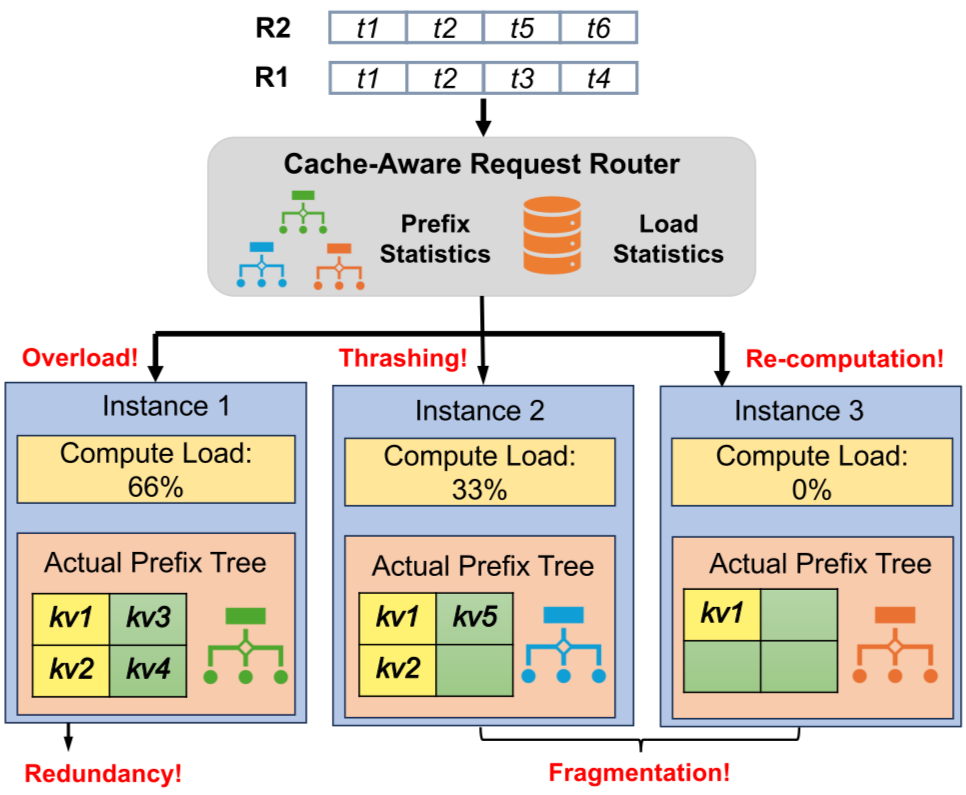
Master KV cache aware routing with llm-d for efficient AI inference ...
Semantic Caching for LLM Inference: GPTCache, Redis Vector Cache, and ...
LLM Integration Unleashed: Elevating Efficiency and Cutting Costs With ...
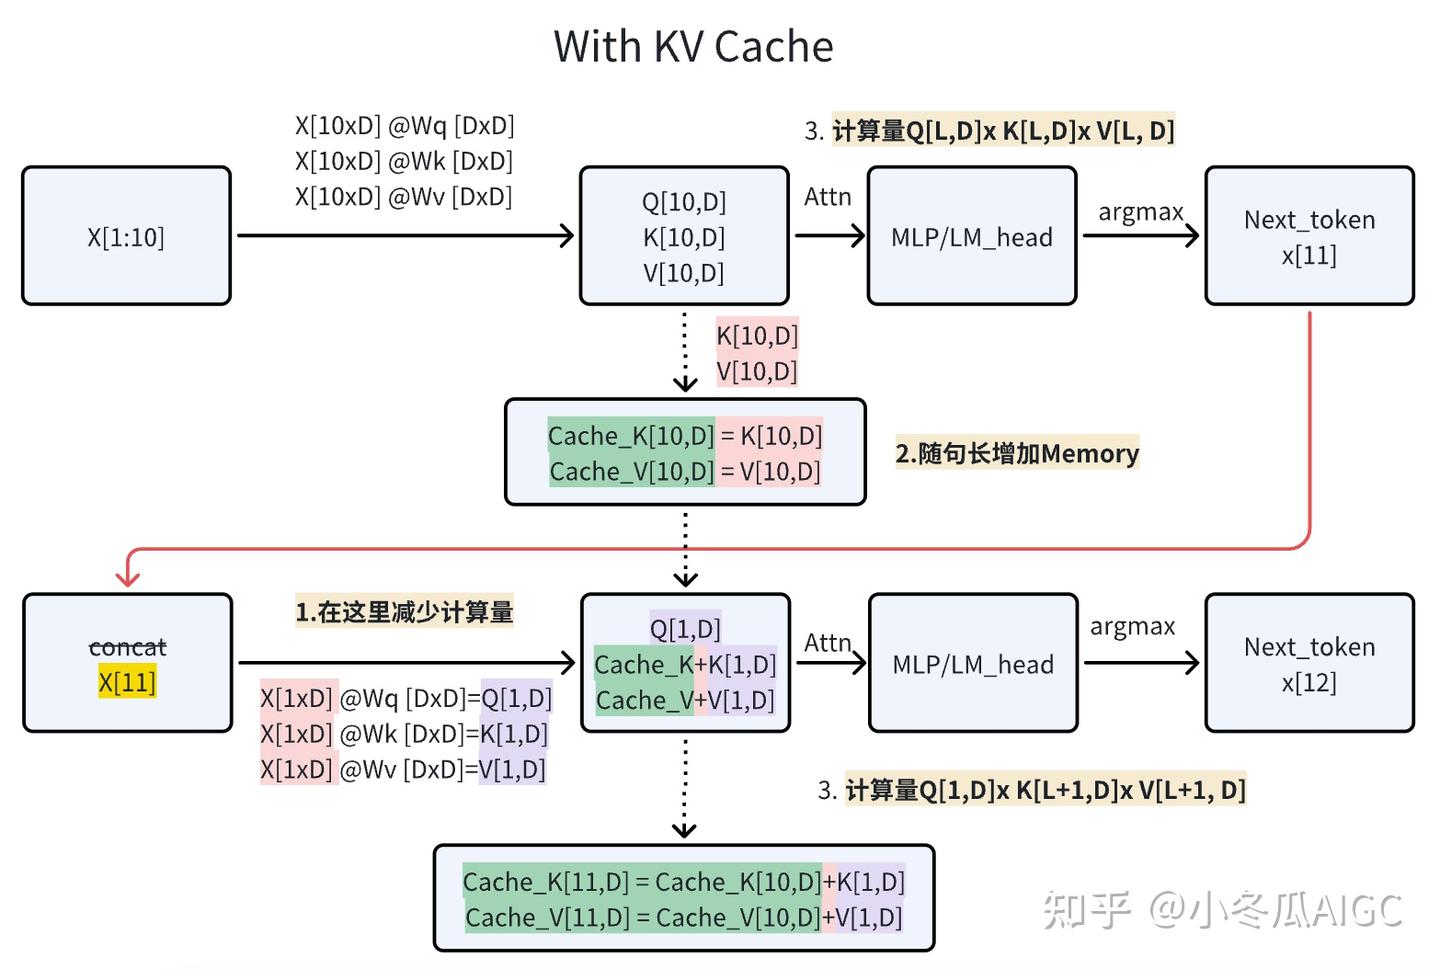
图文详解LLM inference:KV Cache - 知乎
LLM Apps: 100x Faster Replies and Drastic Cost Cut using GPTCache ...
Cut LLM Costs and Latency with ScyllaDB Semantic Caching | ScyllaDB
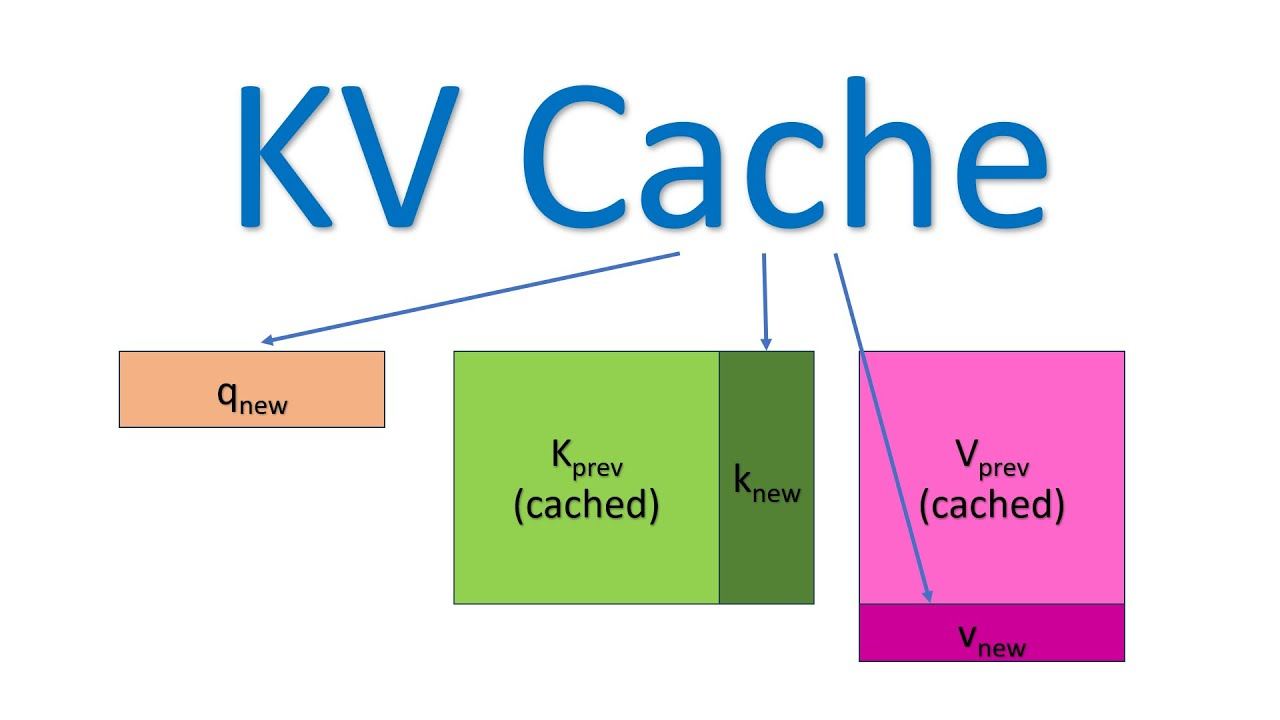
How To Reduce LLM Decoding Time With KV-Caching!
Memory Optimization in LLMs: Leveraging KV Cache Quantization for ...
GitHub - nirtz14/LLM-Cache-Optimization: Context-aware LLM caching ...
LLM推理的KV cache - 知乎
LLM Inference Guide: 12 Proven Ways To Speed Up AI Models
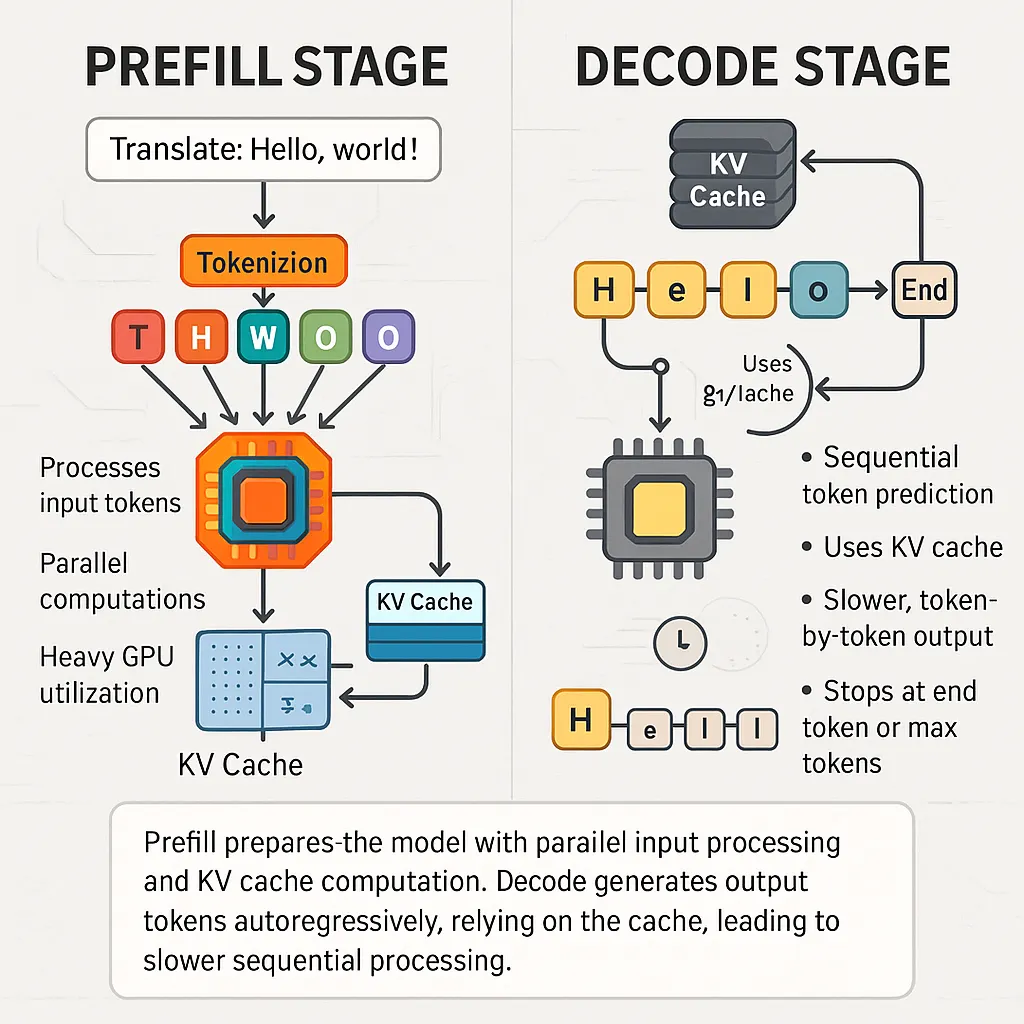
Understanding the Two Key Stages of LLM Inference: Prefill and Decode ...
Paper page - LMCache: An Efficient KV Cache Layer for Enterprise-Scale ...
Asynchronous Verified Semantic Caching for Tiered LLM Architectures
[논문 리뷰] Mooncake: A KVCache-centric Disaggregated Architecture for LLM ...
Reduce LLM Latency : KV Caching. How to serve LLMs ? | by Anuva Sharma ...
Self-Consistency with Chain of Thought (CoT-SC) | by Johannes Koeppern ...
AI(LLM) 모델 성능 하락과 비용 최적화 대응 전략 - TILNOTE
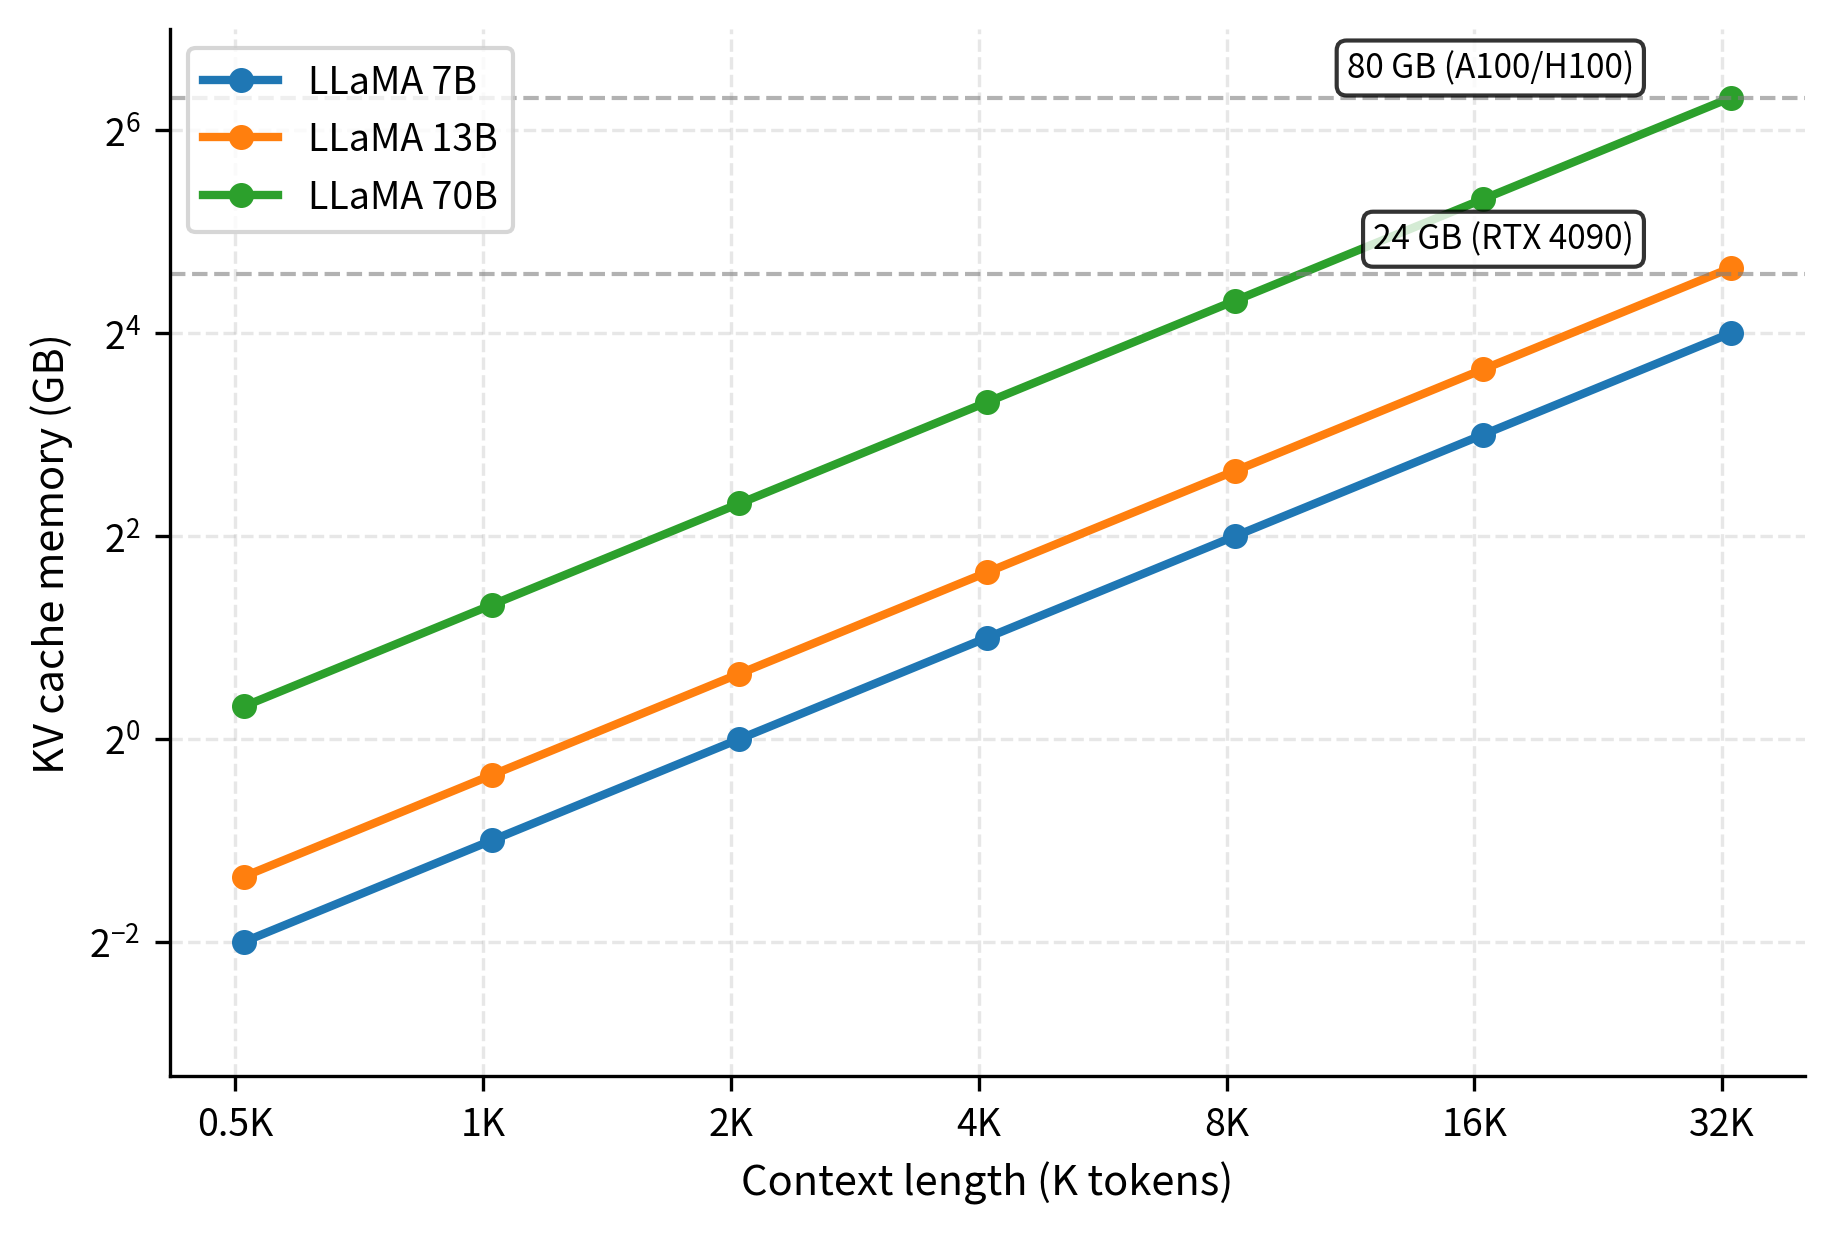
LLM: How to Calculate KV Cache. A single Llama 3.1 405B user at 128k ...
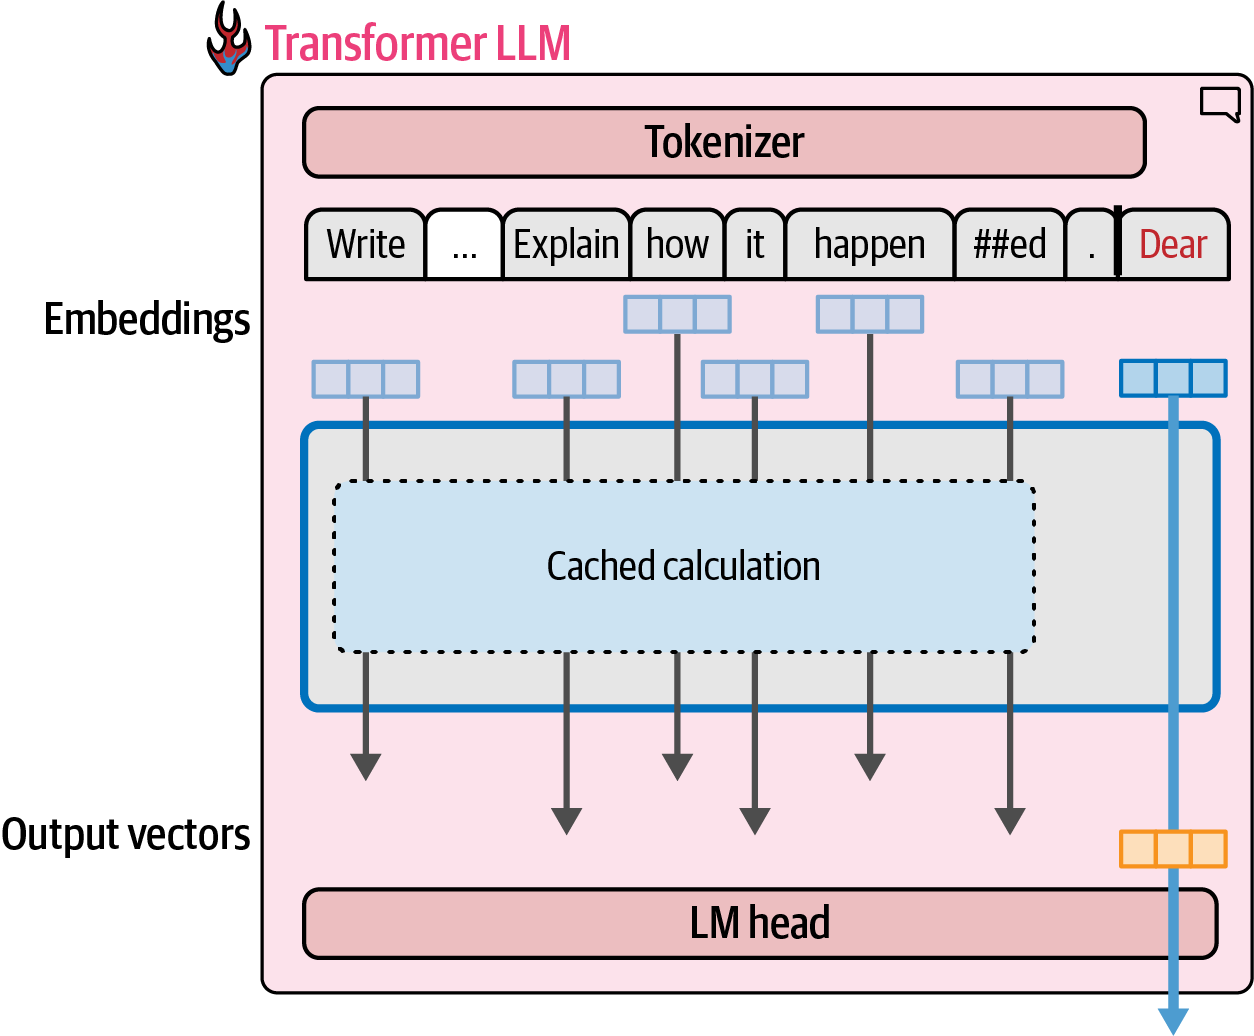
Hands-On Large Language Models
Mohammad Jamalianpour - DEV Community
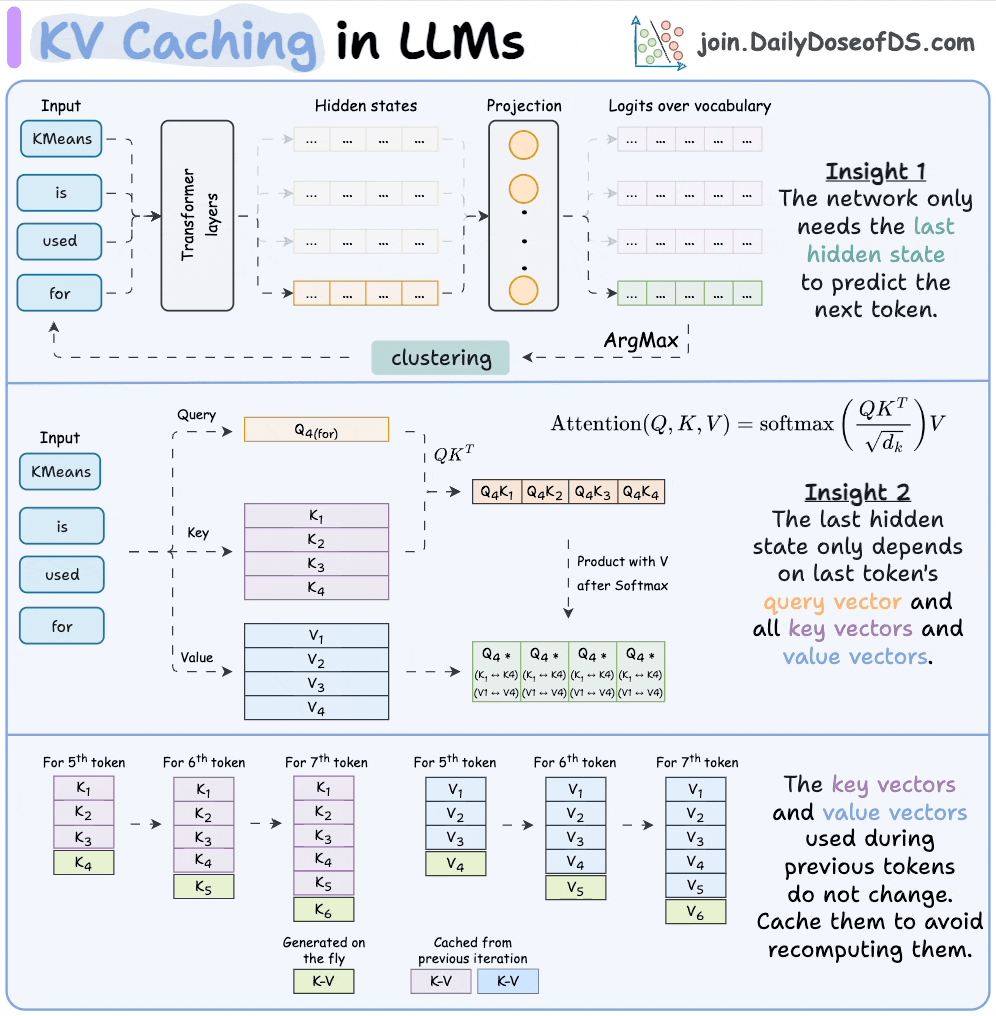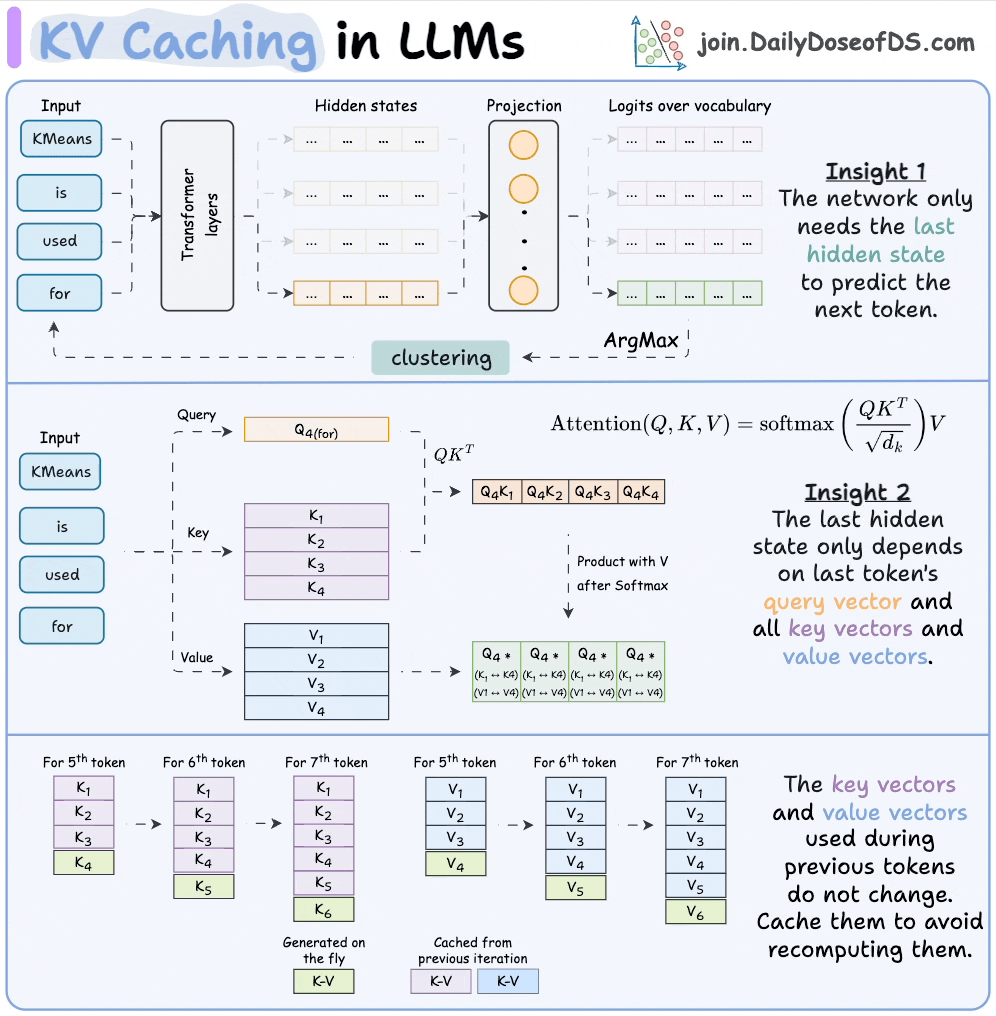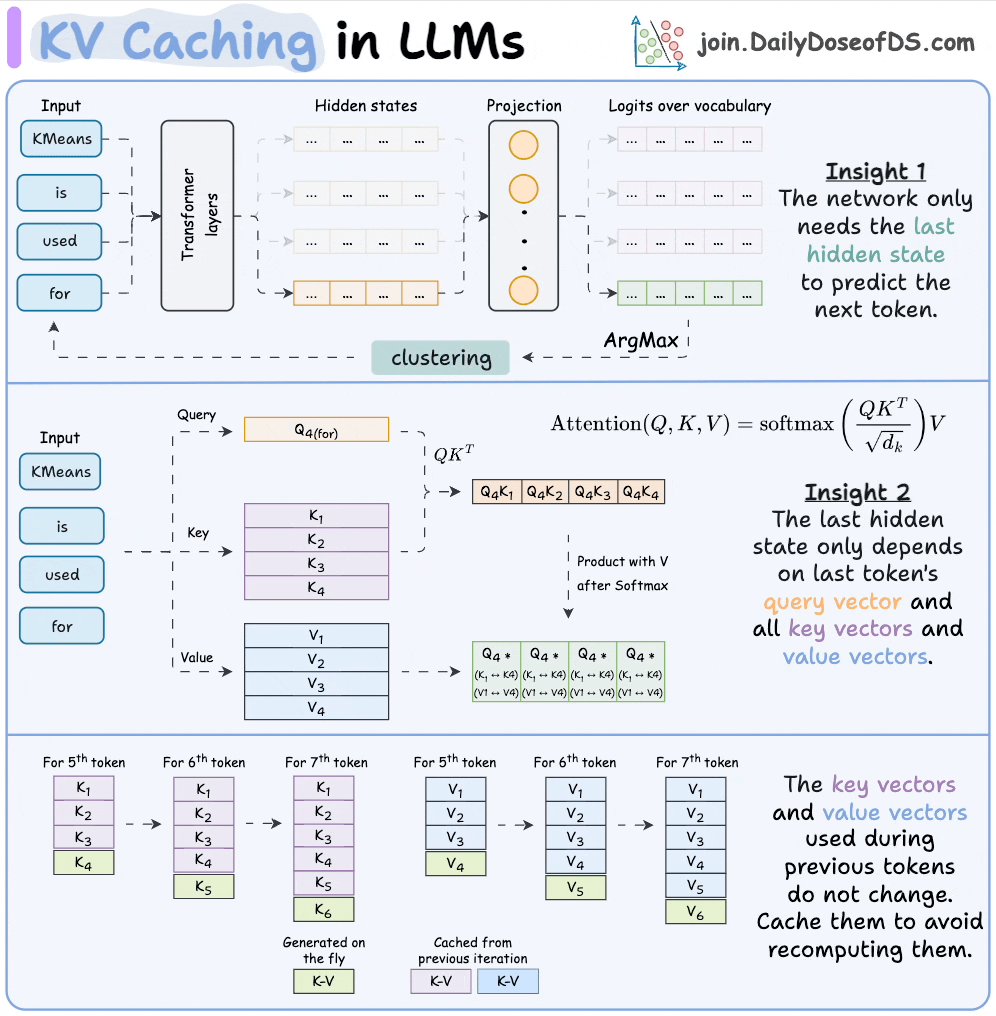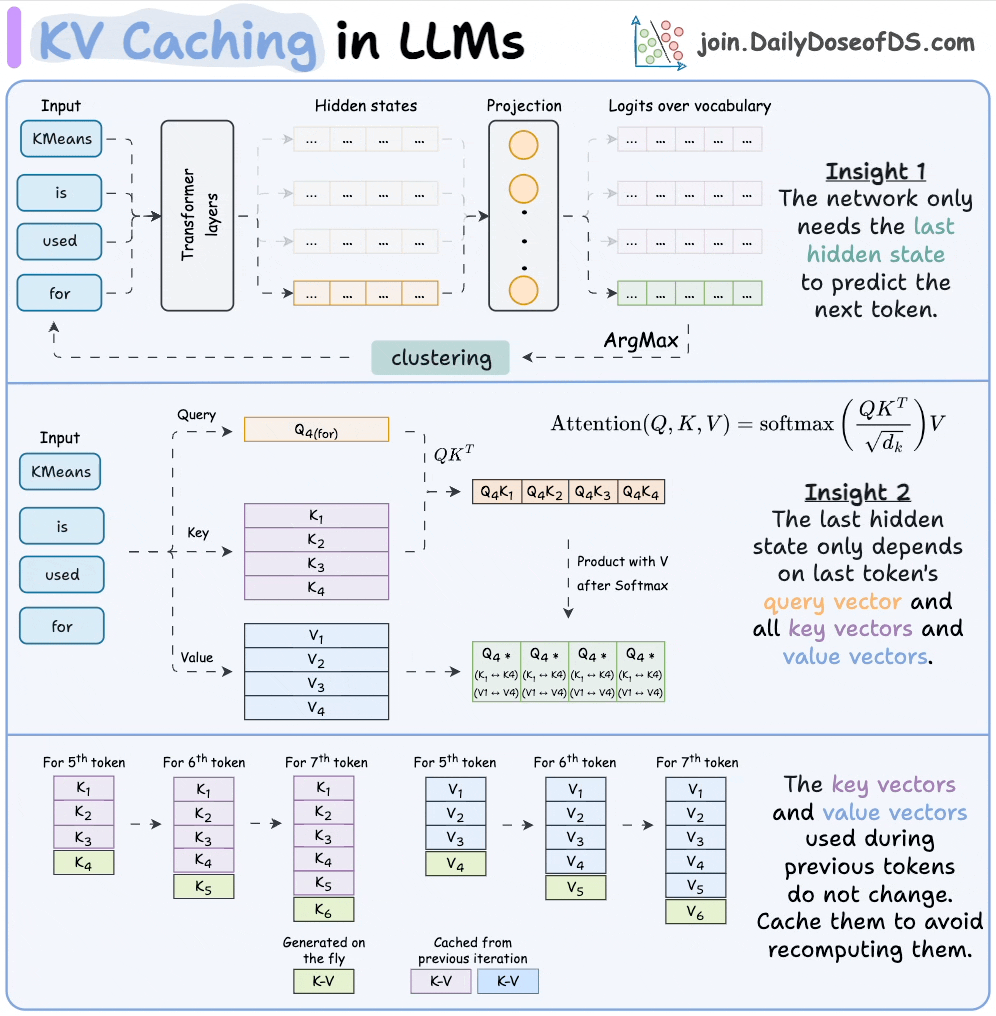
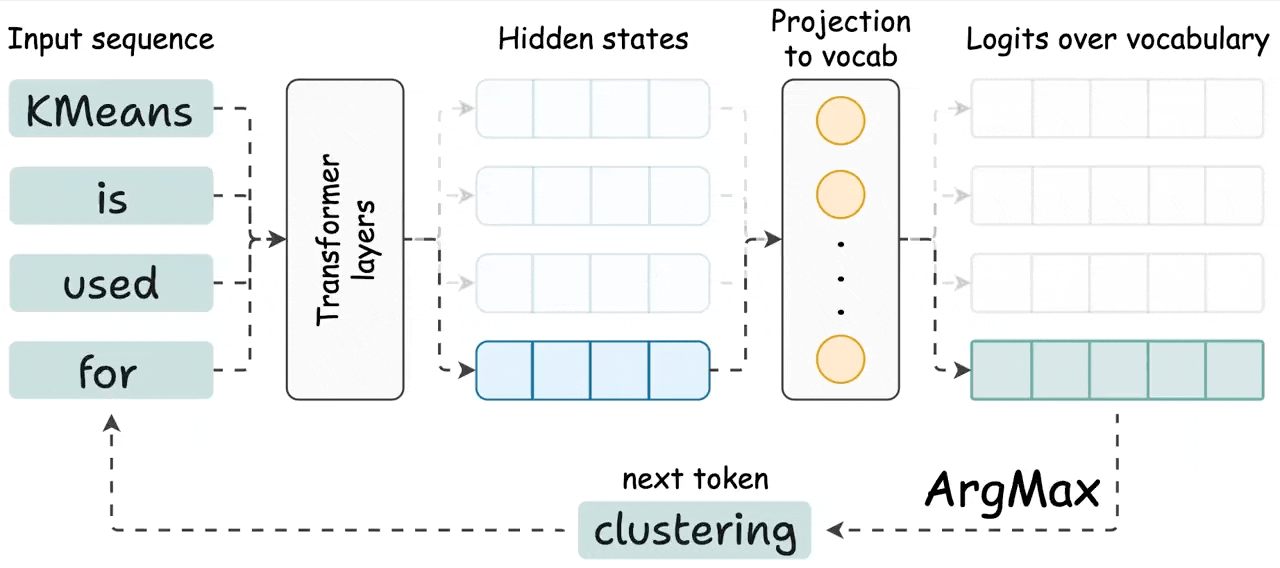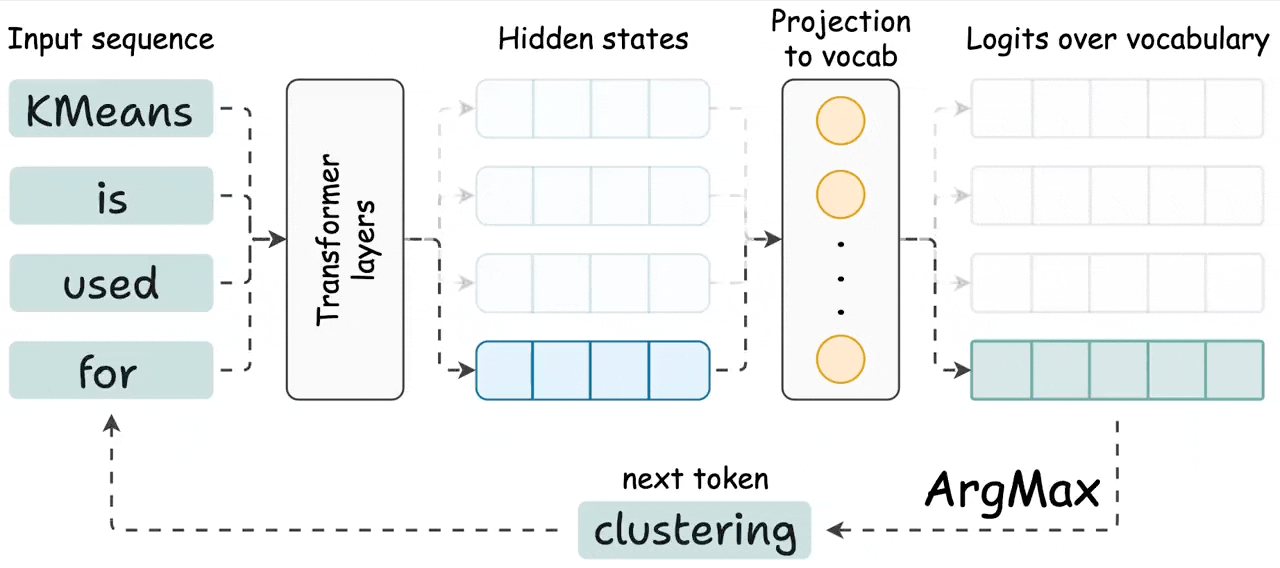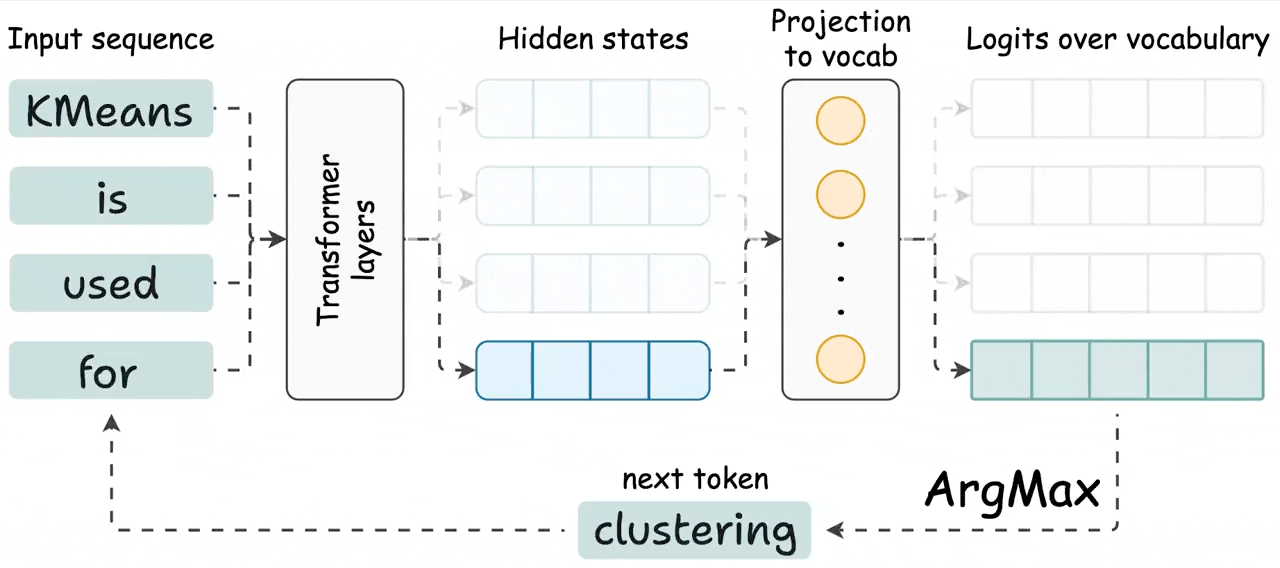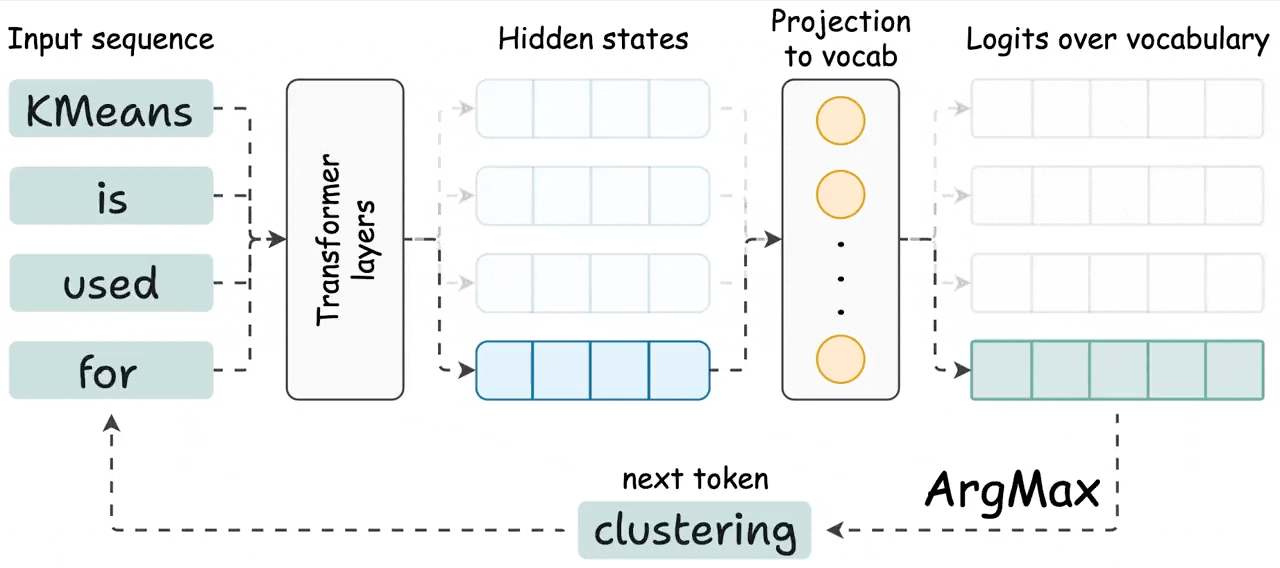
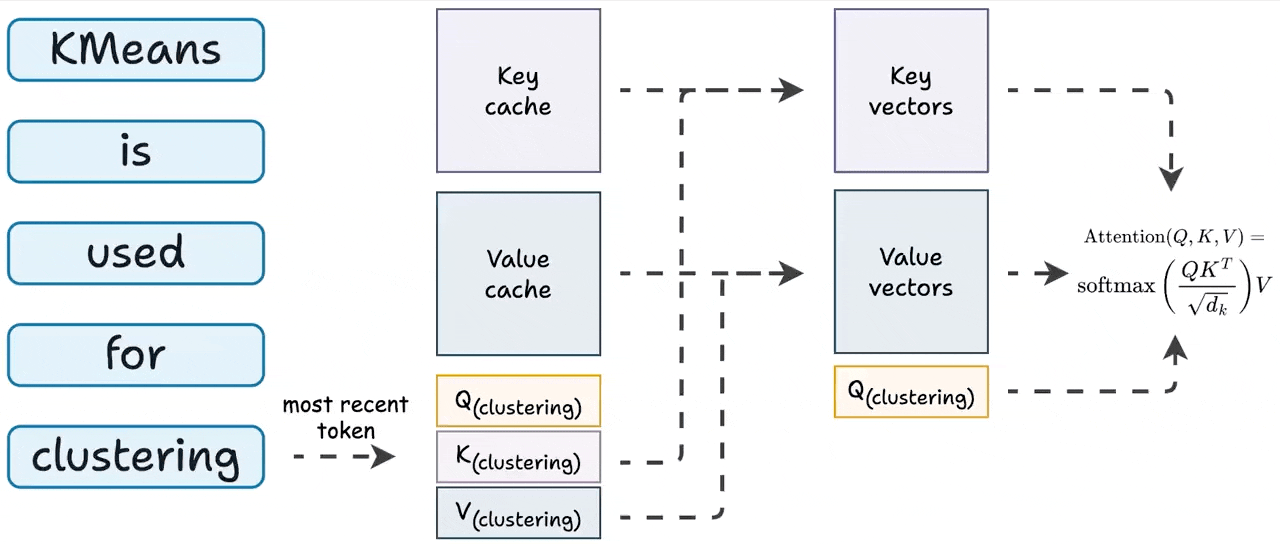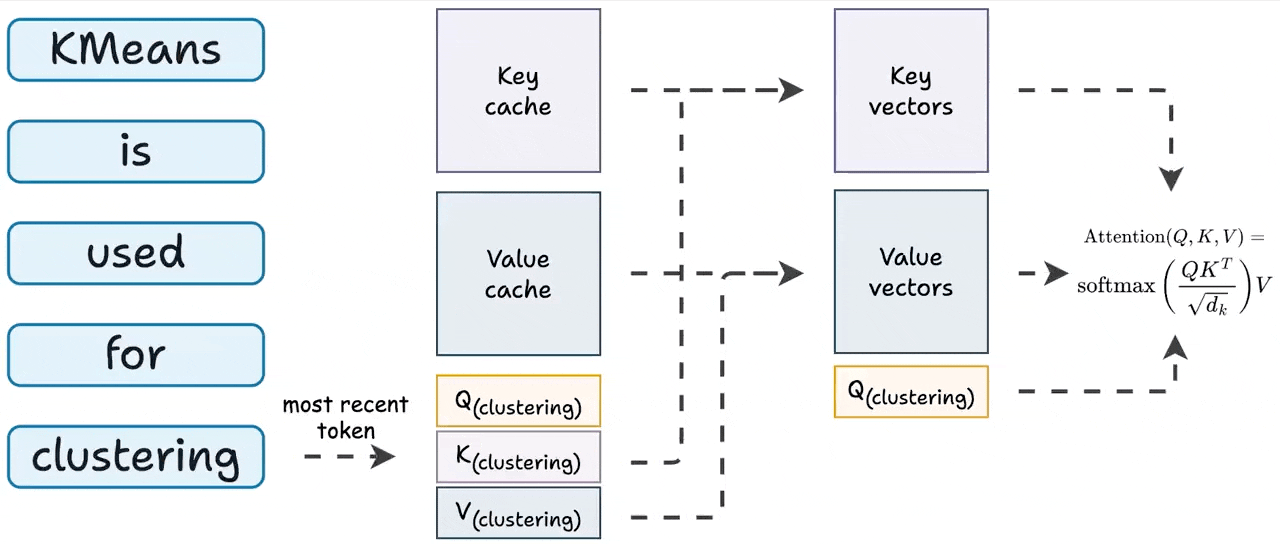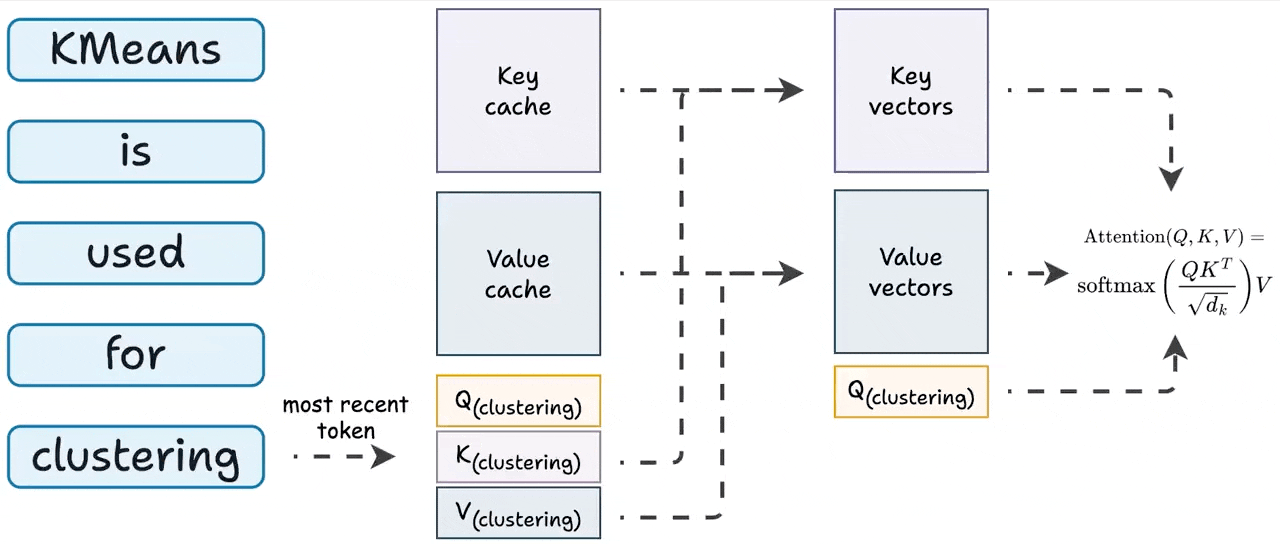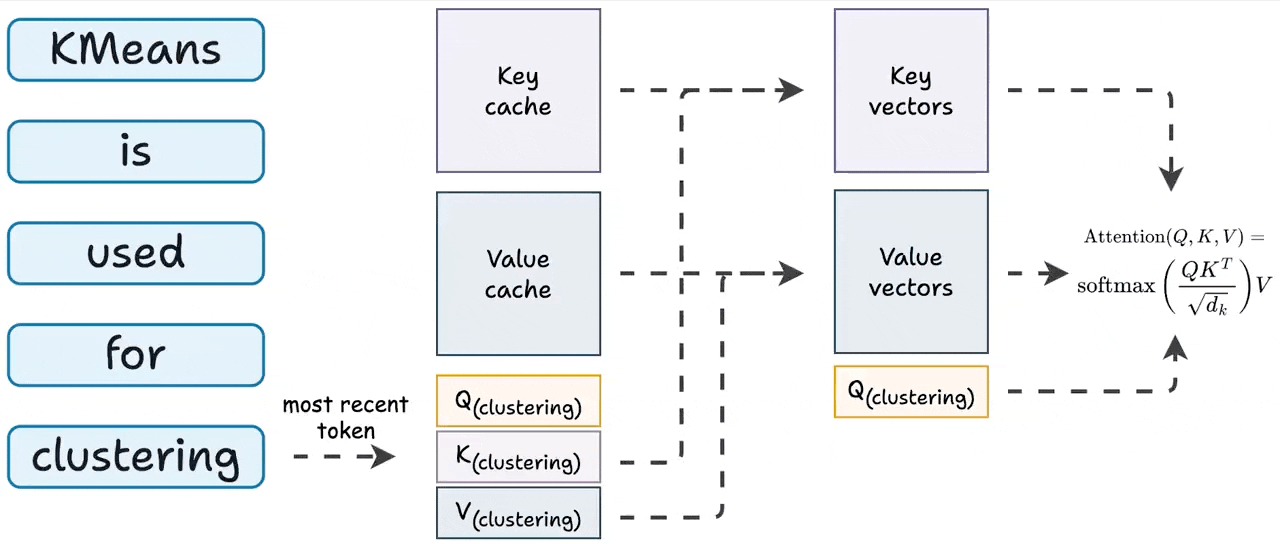
KV Caching in LLMs, Explained Visually. - by Avi Chawla
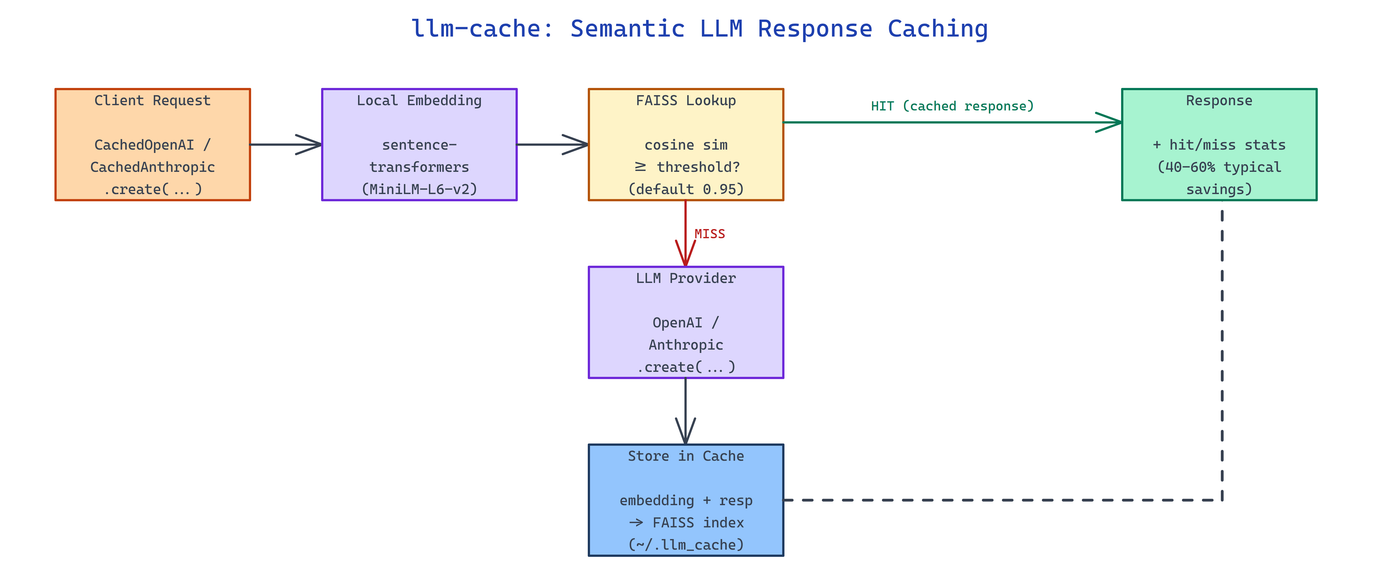
llm-cache: Semantic Response Caching for OpenAI and Anthropic SDKs
Introducing Semantic Caching and a Dedicated MongoDB LangChain Package ...
【手撕LLM-KVCache】显存刺客的前世今生--文末含代码 - 知乎
Medium
[LLM]KV cache详解 图示,显存,计算量分析,代码 - 知乎
The KV Cache: How LLMs Remember - by Rajesh Pandey
RAG Powered Document QnA & Semantic Caching with Gemini AI
Meet 'kvcached': A Machine Learning Library to Enable Virtualized ...
KV Caching in LLMs, explained visually
Awesome-Efficient-LLM/kv_cache_compression.md at main · horseee/Awesome ...
Meet 'kvcached': A Machine Studying Library to Allow Virtualized ...
LMCache:KV缓存管理 - 汇智网
LLM中的KV Cache优化技术_llm kv cache-CSDN博客
The Weekly Edge: Practical Gremlin, Multimodal Graphs, Semantic Caching ...
kv_cache Explained: How It Enhances vLLM Inference - Cloudthrill
Shadow in the Cache: Unveiling and Mitigating Privacy Risks of KV-cache ...
【手撕LLM - KV Cache】为什么没有Q-Cache?? - 知乎
Maximizing Efficiency: A Comprehensive Guide to GPU and Memory ...